<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator><link href="https://rse.shef.ac.uk/feed.xml" rel="self" type="application/atom+xml" /><link href="https://rse.shef.ac.uk/" rel="alternate" type="text/html" /><updated>2026-09-04T16:09:15+01:00</updated><id>https://rse.shef.ac.uk/feed.xml</id><title type="html">Research Software Engineering Sheffield</title><subtitle>Research Software Engineers (RSEs) are the people behind research software. This website is designed as a hub for Sheffield academics and researchers seeking help with research software and as a community for research software engineers.
</subtitle><entry><title type="html">A Novel Deep Learning Architecture for Multi-label Text Classification of Patent Data</title><link href="https://rse.shef.ac.uk/blog/2026-02-18-innovation-project/" rel="alternate" type="text/html" title="A Novel Deep Learning Architecture for Multi-label Text Classification of Patent Data" /><published>2026-02-18T12:00:00+00:00</published><updated>2026-02-18T12:00:00+00:00</updated><id>https://rse.shef.ac.uk/blog/2026-02-18-innovation-project</id><content type="html" xml:base="https://rse.shef.ac.uk/blog/2026-02-18-innovation-project/"><![CDATA[<h2 id="overview">Overview</h2>

<p>Text classification is a foundational problem in natural language processing (NLP), allowing us to automatically assign
predefined labels to massive volumes of unstructured text. In the context of technological innovations, one of the most
valuable applications of text classification is automating the assignment
of <a href="https://www.wipo.int/en/web/classification-ipc">International Patent Classification (IPC)</a> hierarchies to technical
documents.</p>

<!--more-->

<p>Historically, this process has been a computationally expensive and time-consuming manual task. While traditional
machine learning methods (like Support Vector Machines or simple Neural Networks) have been used in the past, they often
require extensive feature engineering and struggle to grasp the nuanced, technical context of patent data.</p>

<p>To tackle this, we developed a robust, state-of-the-art methodology capable of semantically understanding technical
patent abstracts and predicting their corresponding IPC labels across multiple hierarchical levels. This
cross-institutional collaborative effort was led by <a href="https://sheffield.ac.uk/economics/staff/academic/enrico-vanino">Dr. Enrico Vanino</a> from
the <a href="https://sheffield.ac.uk/economics">University of Sheffield’s School of Economics</a>
and <a href="https://www.henley.ac.uk/people/professor-carlo-corradini">Prof. Carlo Corradini</a> from
the <a href="https://www.henley.ac.uk/">Henley Business School at University of Reading</a>, with developer support provided
by <a href="https://www.farhadallian.co.uk/">Dr. Farhad Allian</a> from the Data Analytics Service
at <a href="https://sheffield.ac.uk/it-services/about/who-we-are-and-what-we-do">University of Sheffield’s IT Services</a>, who
developed the model architecture, codebase, and technical report. This post provides a look under the hood at our data
processing pipeline, model architecture, and evaluation strategy used as part of this research.</p>

<h2 id="the-data-challenge-navigating-label-scarcity-and-imbalance">The Data Challenge: Navigating Label Scarcity and Imbalance</h2>

<p style="text-align: center;"><img src="/assets/images/2026-02-18-innovation-project/figure1.png" alt="Corpus statistics of the PATSTAT dataset" class="img-fluid" id="fig1" /></p>
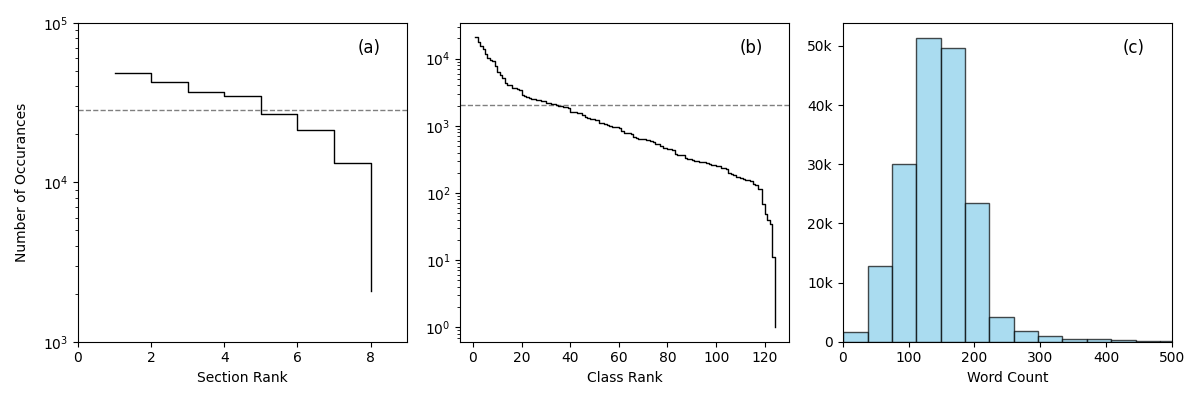
<p style="text-align: center;"><em><strong>Figure 1</strong>: Corpus statistics of the PATSTAT dataset. (a) shows the label count distribution for the Section level. The
dashed line shows the mean value. 50% of labels are above the mean value. (b) same as (a), but for the Class level. Only
27% of labels are above the mean value. (c) shows the word-count distribution of the abstracts.</em></p>

<p>Training any multi-label deep learning model requires a massive amount of high-quality data, especially given the
hundreds of possible hierarchical IPC classifications. To build out our classification architecture, we leveraged
<a href="https://www.epo.org/en/searching-for-patents/business/patstat">PATSTAT</a>, a global database containing over 130 million patent documents. By sampling 177,000 relevant patents for this
research, we curated a comprehensive training dataset mapping technical abstracts to verified multi-label IPC codes (at
the broader “Section” and “Class” levels). This allowed our model to learn the complex linguistic patterns associated
with diverse technological domains. <a href="#fig1">Figure 1</a> provides an overview of the corpus statistics used in our sampled training
dataset, including the label distributions for the two IPC labels used in our study, and the mean word count per
abstract.</p>

<p>As with all text classification problems, one major hurdle in patent data is the severe class imbalance. The label space
is highly skewed toward dominant fields like electronics or chemistry, while niche or emerging domains remain sparsely
represented. One approach is to process the data by upsampling the frequency of low-occurring labels before training the
model. However, to ensure the model accurately reflects this real-world distribution, we intentionally avoided any
artificially upsampling of rare labels in our approach. Instead, we relied on strict stratified sampling across our
training, validation, and test splits that mimics the raw dataset’s proportions and reduces the model’s bias. This
guarantees that rare technological domains are preserved and adequately represented across all phases of model
development. A summary of the data splits is shown in <a href="#tab1">Table 1</a>.</p>

<table class="table table-bordered table-striped table-hovered" id="tab1">
  <thead>
    <tr>
      <th style="text-align: left">Splits</th>
      <th style="text-align: right">Total labels (Section)</th>
      <th style="text-align: right">Total labels (Class)</th>
      <th style="text-align: right">Average labels per patent (Section)</th>
      <th style="text-align: right">Average labels per patent (Class)</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left">Train</td>
      <td style="text-align: right">8</td>
      <td style="text-align: right">123</td>
      <td style="text-align: right">1.27</td>
      <td style="text-align: right">1.42</td>
    </tr>
    <tr>
      <td style="text-align: left">Val</td>
      <td style="text-align: right">8</td>
      <td style="text-align: right">123</td>
      <td style="text-align: right">1.26</td>
      <td style="text-align: right">1.41</td>
    </tr>
    <tr>
      <td style="text-align: left">Test</td>
      <td style="text-align: right">8</td>
      <td style="text-align: right">124</td>
      <td style="text-align: right">1.28</td>
      <td style="text-align: right">1.44</td>
    </tr>
  </tbody>
</table>

<p style="text-align: center;"><em><strong>Table 1</strong>: Train-val-test statistics following the stratified sampling. Note that there exists more than one label per
patent on average.</em></p>

<h2 id="our-approach-fine-tuning-and-hierarchical-masking">Our Approach: Fine-tuning and Hierarchical Masking</h2>

<p style="text-align: center;"><img src="/assets/images/2026-02-18-innovation-project/figure2.png" alt="Workflow diagram" class="img-fluid" id="fig2" /></p>
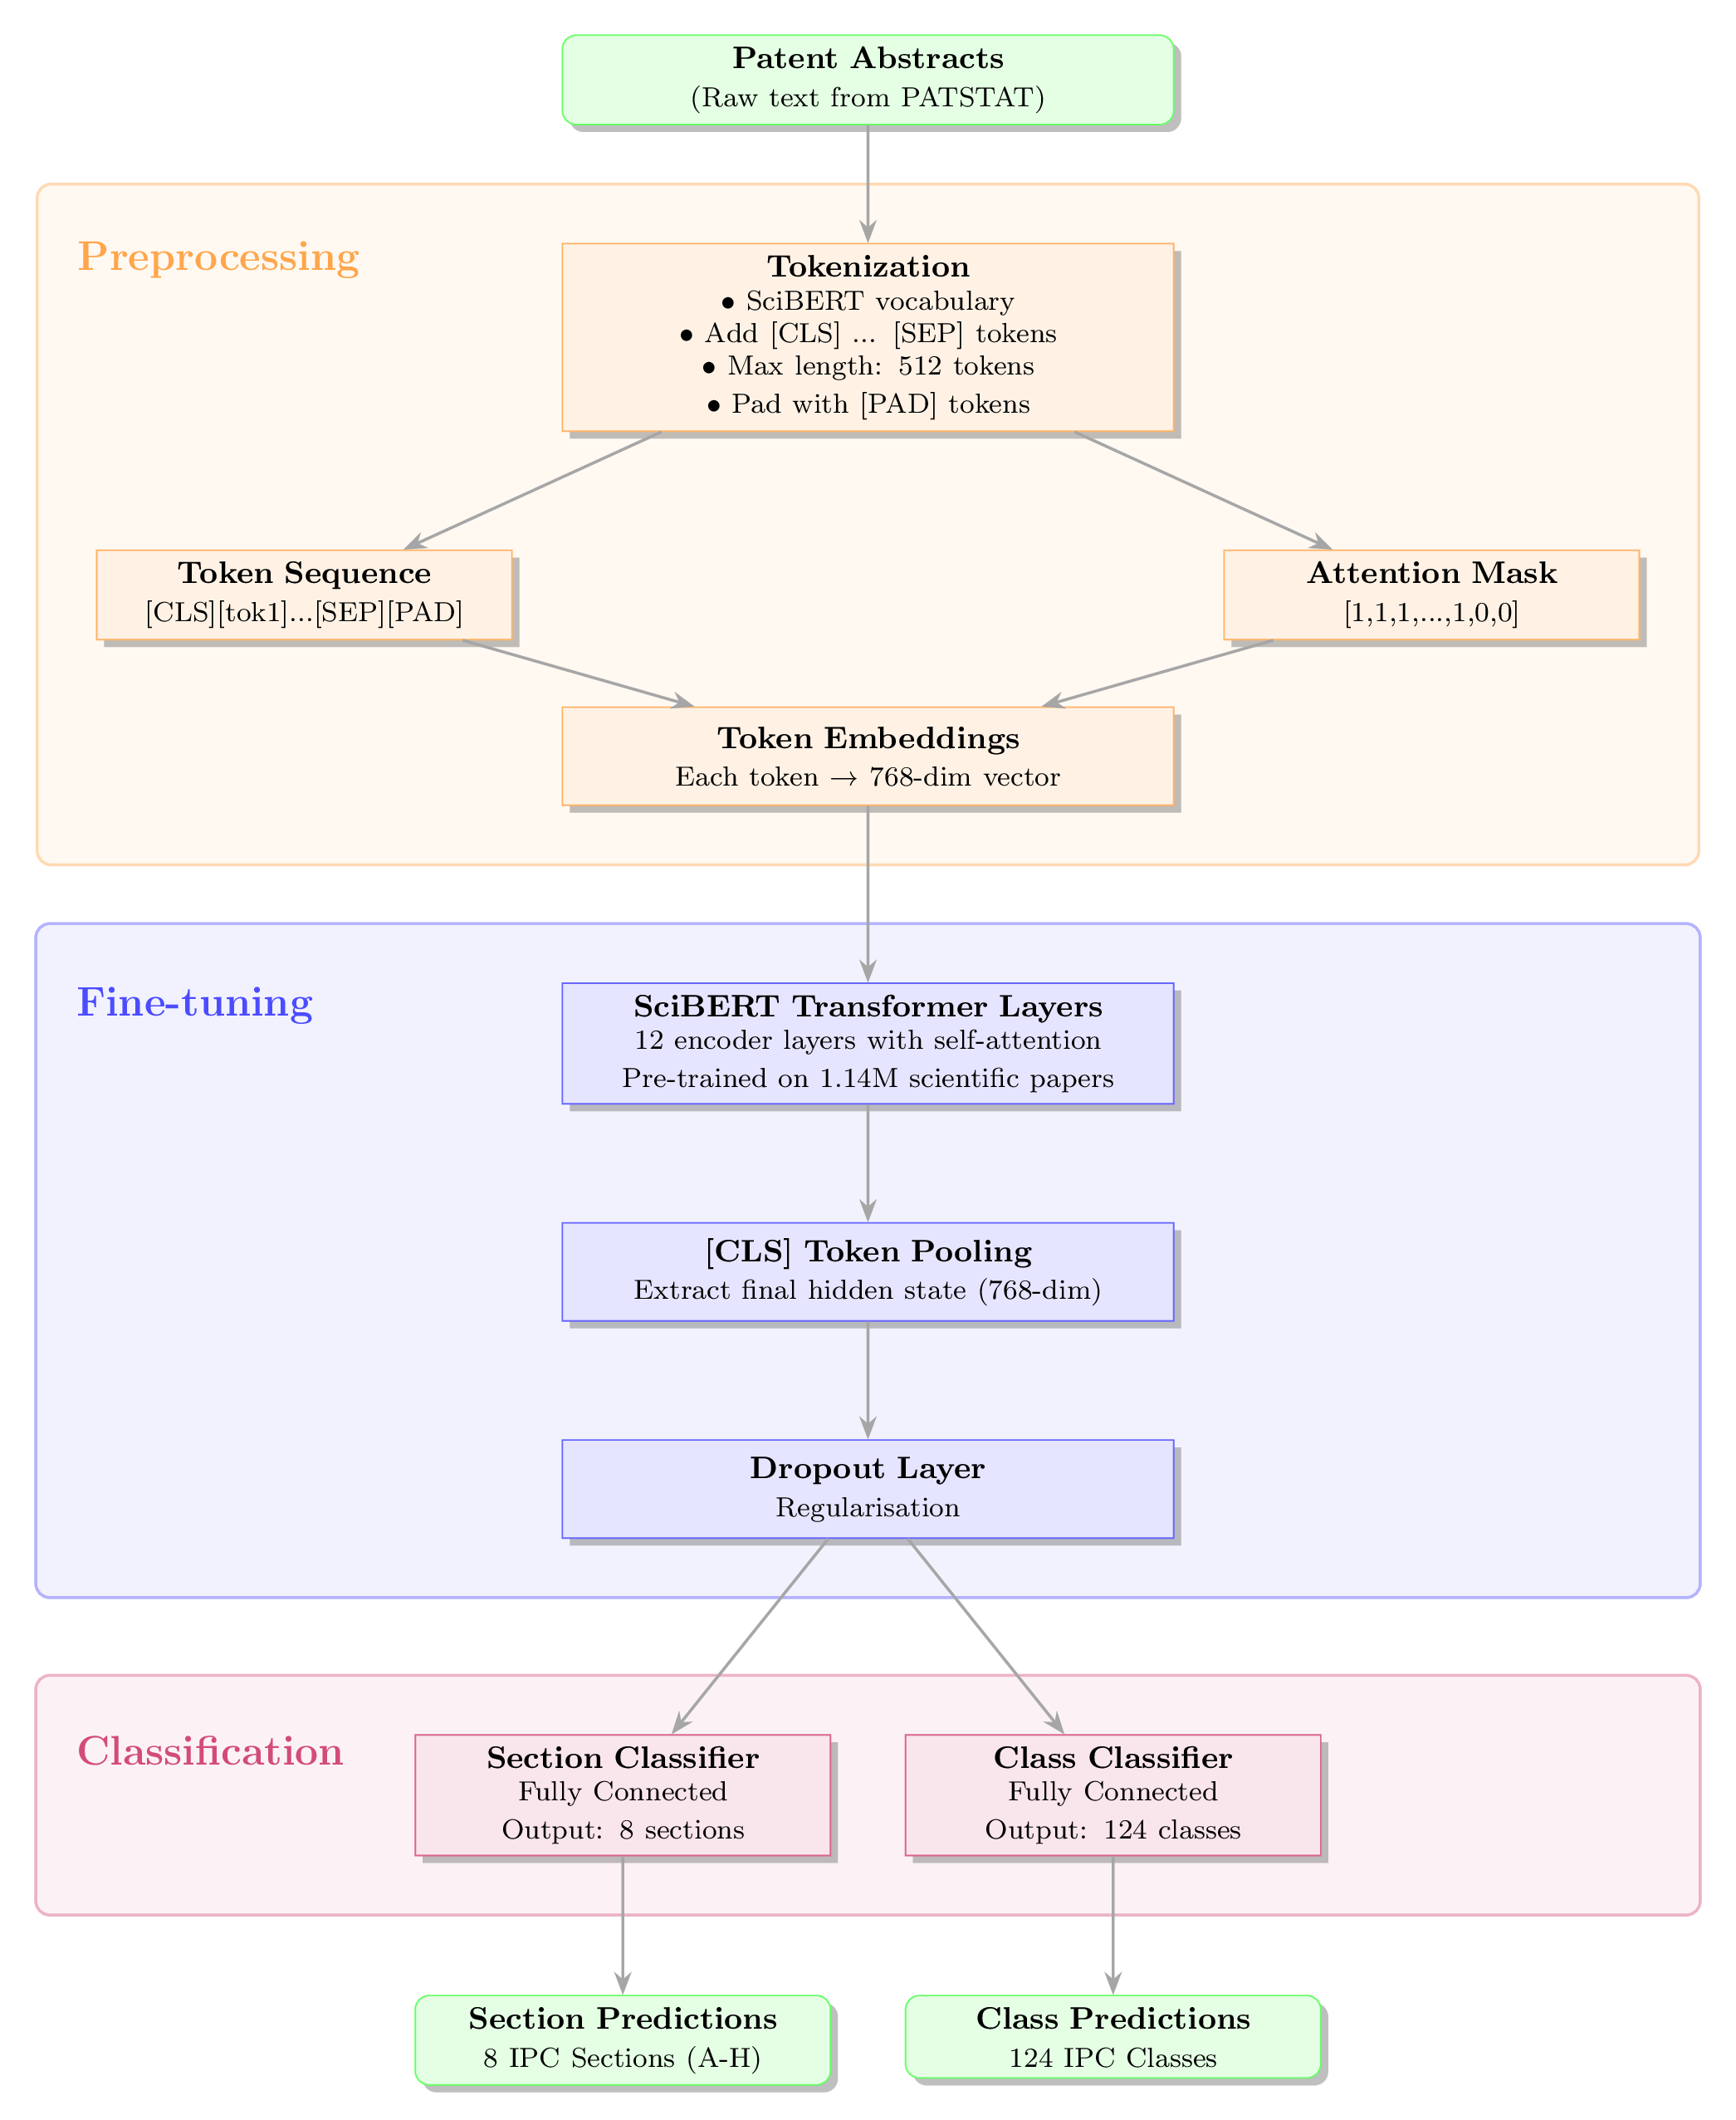
<p style="text-align: center;"><em><strong>Figure 2</strong>: Schematic diagram of our workflow demonstrating the preprocessing, fine-tuning, and classification stages.</em></p>

<p>To capture the highly specialised jargon of technical abstracts, we moved beyond standard language models (like the
original BERT, which is trained on general text like Wikipedia) and utilised <a href="https://aclanthology.org/D19-1371/">SciBERT</a>. SciBERT is a domain-specific transformer
pre-trained on 1.14 million scientific papers, making it suitable to ingest complex, domain-specific abstracts. The
architecture of our multi-label text classification pipeline involves the following three main steps:</p>

<ol>
  <li>
    <p><strong>Preprocessing:</strong> Raw abstracts are tokenised (up to a maximum sequence length of 512 tokens). Each token is mapped to
a 768-dimensional embedding vector, and the final hidden state of the classification token (<code class="language-plaintext highlighter-rouge">[CLS]</code>) is pooled to create a
single, dense semantic representation of the entire abstract.</p>
  </li>
  <li>
    <p><strong>Fine-tuning:</strong> The token embeddings are passed into the pre-trained SciBERT layer to perform fine-tuning. <code class="language-plaintext highlighter-rouge">[CLS]</code> token
pooling is performed to represent the global information of each abstract. The pooled output passes through a dropout
layer (to reduce overfitting) and feeds into two distinct, fully connected classification heads; one for predicting the
IPC “Section” (the parent level) and one for the IPC “Class” (the child level).</p>
  </li>
  <li>
    <p><strong>Predictions:</strong> Because IPC codes are strictly hierarchical, we leveraged this property and engineered the model to
mask invalid parent-child combinations during predictions. For instance, if the model confidently predicts that a text
belongs to Section “A”, the subsequent class predictions are constrained to only output classes that begin with “A” (
e.g., A01). This masking approach drastically reduces the effective label space (from 124 possible classes down to just
the relevant ones for that section), cutting through the noise and improving the signal-to-noise ratio. The end-to-end workflow is demonstrated in <a href="#fig2">Figure 2</a>.</p>
  </li>
</ol>

<p>The model was fine-tuned to minimise a weighted combination of binary cross-entropy losses across the two hierarchical
levels with respect to the frequency of IPC labels. To handle the computational load of the 110-million parameter model,
training was executed using mixed-precision (FP16) on a single node equipped with dual AMD EPYC CPUs and an
NVIDIA A100 GPU on <a href="https://docs.hpc.shef.ac.uk/en/latest/index.html#gsc.tab=0">Sheffield University’s HPC cluster, Stanage</a>.</p>

<h2 id="evaluation-strategy-using-standard-and-hierarchical-metrics">Evaluation Strategy: Using Standard and Hierarchical Metrics</h2>

<p style="text-align: center;"><img src="/assets/images/2026-02-18-innovation-project/figure3.png" alt="Training and evaluation performances" class="img-fluid" id="fig3" /></p>
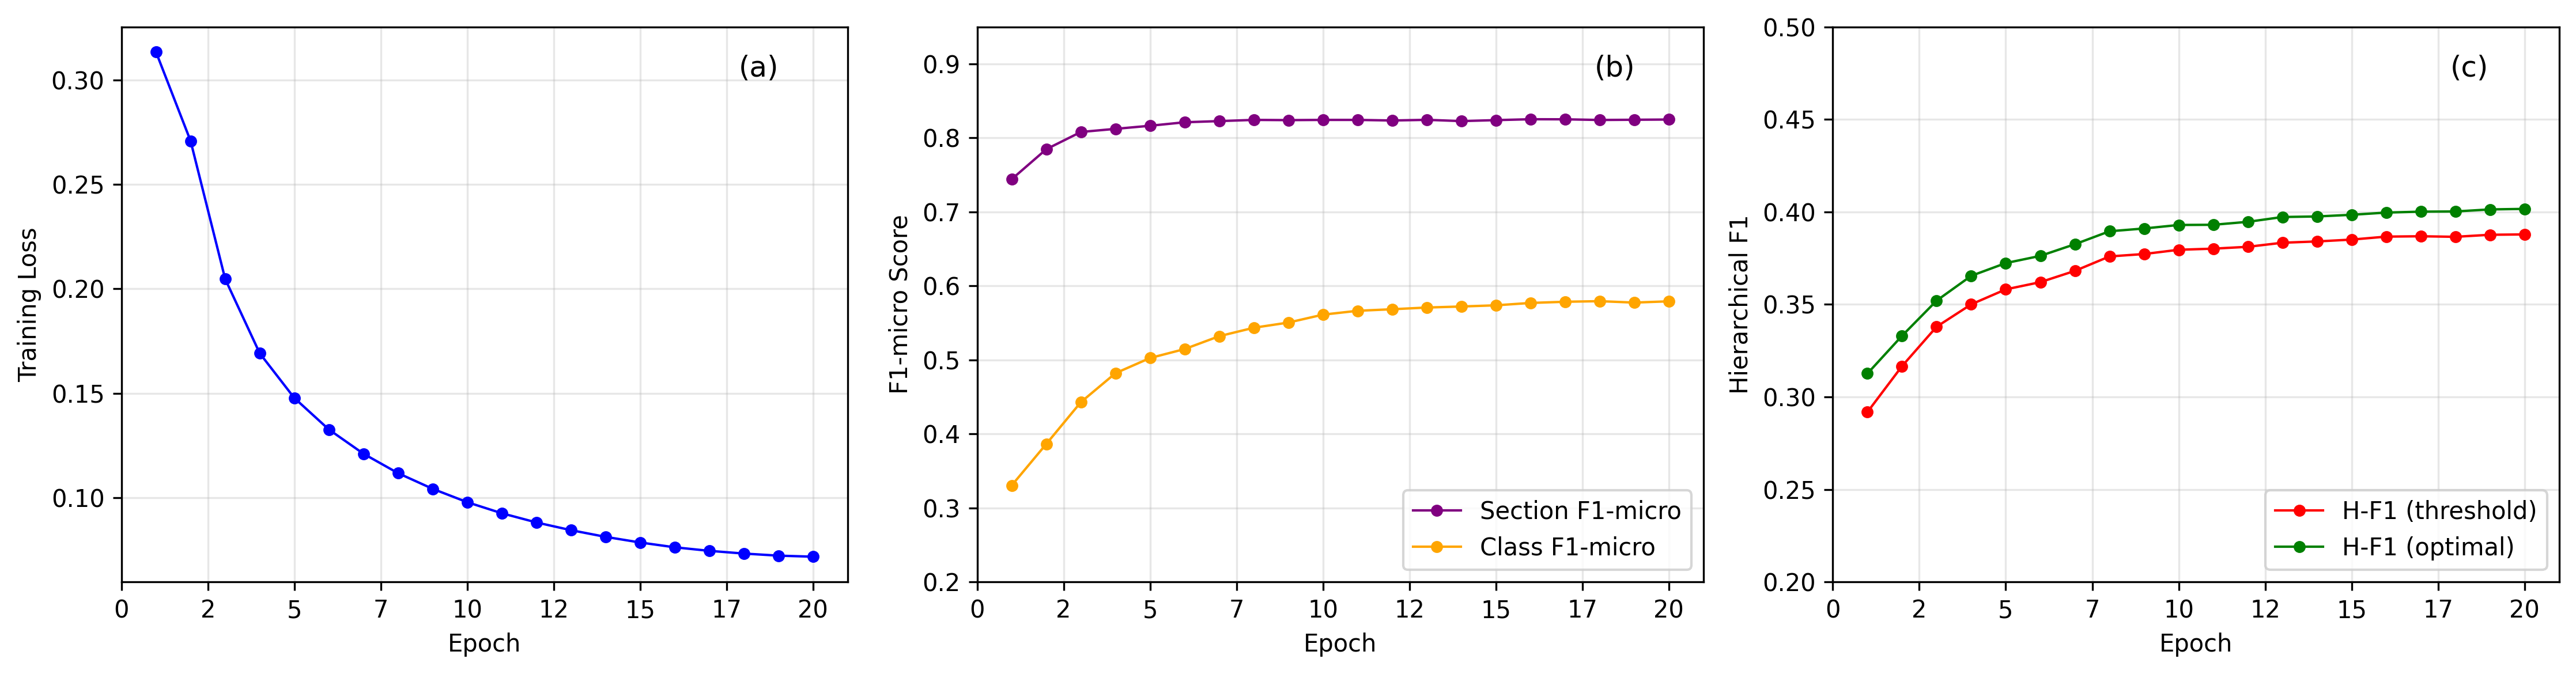
<p style="text-align: center;"><em><strong>Figure 3</strong>: Training and evaluation performances of the hierarchical classifier across 20 epochs. (a) Training loss
exhibits a smooth convergence. (b) Section-level F1-micro rapidly plateaus at 82% while class-level performance
continues improving from 33% before stablising around 58%, highlighting the difficulty in predicting within a large
label space. (c) Hierarchical F1 scores show consistent improvement with an optimisation approach providing a 3-4% gain
over specified thresholds, reaching a final optimised H-F1 of 40%.</em></p>

<p>Evaluating a model trained on heavily imbalanced, hierarchical data requires looking beyond basic accuracy thresholds.
During validation, we treated the task as a multi-label classification problem, looking at both <a href="https://scikit-learn.org/stable/modules/model_evaluation.html#from-binary-to-multiclass-and-multilabel">micro metrics</a> (e.g.
F1-micro, which favour frequent classes) and macro metrics (e.g. F1-macro, which treat rare niche classes equally) to
objectively quantify the model’s performance.</p>

<p>Importantly, we also implemented hierarchical metrics to expand our evaluation strategy. Standard flat metrics, such as
those described above, treat all misclassifications as equally incorrect. Hierarchical metrics, however, award partial
credit when predictions are taxonomically related. For instance, if the model predicts class “B01” instead of the true
label “B23”, it receives partial credit because it correctly identified the broader technological domain (Section B).
This proves highly valuable for mapping interdisciplinary innovations that might span multiple related fields.</p>

<table class="table table-bordered table-striped table-hovered" id="tab2">
  <thead>
    <tr>
      <th style="text-align: left">Level</th>
      <th style="text-align: right">F1 Micro</th>
      <th style="text-align: right">F1 Macro</th>
      <th style="text-align: right">Precision Micro</th>
      <th style="text-align: right">Recall Micro</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left">Section</td>
      <td style="text-align: right">0.8242</td>
      <td style="text-align: right">0.8061</td>
      <td style="text-align: right">0.8396</td>
      <td style="text-align: right">0.8094</td>
    </tr>
    <tr>
      <td style="text-align: left">Class</td>
      <td style="text-align: right">0.5434</td>
      <td style="text-align: right">0.1626</td>
      <td style="text-align: right">0.6063</td>
      <td style="text-align: right">0.4924</td>
    </tr>
  </tbody>
</table>

<p style="text-align: center;"><em><strong>Table 2</strong>: Sample evaluation metrics showing the micro (frequent labels) and macro (rare labels) scores.</em></p>

<h2 id="summary-and-future-work">Summary and Future Work</h2>

<p>This work represents a significant step toward automating and improving the accuracy of patent categorisation at scale.
It has the potential to enhance patent office workflows and enable more sophisticated analyses of technological
landscapes. While the model currently serves as a research prototype, we envision deployment scenarios where it could
assist patent examiners in preliminary classification tasks or support innovation analysts in mapping emerging
technological trends across large patent portfolios. The framework’s modular design also makes it adaptable to other
hierarchical text classification domains beyond patents. A publication of this work is currently in press.</p>

<p>While the model architecture establishes a powerful methodology for hierarchical text classification of patent data,
there’s still room to grow. Future iterations of this approach can investigate advanced attention mechanisms to better
exploit the hierarchical structure of IPC labels, incorporate richer technical details found in full patent claims
rather than just abstracts, and explore specialised neural architectures explicitly designed to mitigate the extreme
class imbalance inherent in patent classification. Hardware considerations may also play an important part in improving
our approach. Training on our 177,000-document corpus required a relatively standard amount of computational resources (
e.g. Dual AMD CPUs and a NVIDIA A100 GPU), however, expanding to the full PATSTAT database of 130+ million patents would
demand distributed training across multiple GPUs or even TPU clusters. Memory bottlenecks from the 768-dimensional
embeddings and 110-million parameters could also be addressed through model distillation, quantisation, or even more
efficient transformer variants.</p>

<h2 id="acknowledgements">Acknowledgements</h2>

<p>This research was supported by the UK’s Economic and Social Research Council (ESRC) with the project name “<em><a href="https://ircaucus.ac.uk/projects-2/exploring-the-link-between-publicly-funded-rd-collaborations-and-regional-technological-development-ffcoe005/">Exploring
the Link between Publicly Funded R&amp;D Collaborations and Regional Technological Development</a></em>” under the grant FFCoE005. A
paper is currently in press.</p>

<h2 id="contact-us">Contact Us</h2>

<p>This research was undertaken by
the <a href="https://sheffield.ac.uk/it-services/about/who-we-are-and-what-we-do">Data Analytics Service (DAS) team at the University of Sheffield’s IT Services</a>.
We offer free consultations, training, and technical collaboration to researchers across all Faculties.</p>

<p>Whether you need help with text classification, natural language processing, complex data pipelines, or machine
learning, our team of Research Technical Professionals (RTPs) in the Data Analytics Service (DAS) and
the <a href="https://rse.shef.ac.uk/">Research Software Engineering Group</a> can help.</p>]]></content><author><name>Farhad Allian</name></author><category term="machine-learning" /><category term="pytorch" /><category term="deep-learning" /><category term="nlp" /><category term="transformers" /><category term="patent-classification" /><summary type="html"><![CDATA[Predicting technological innovations using deep learning]]></summary></entry><entry><title type="html">Managing Research Code at Sheffield: Getting Started with GitHub Organisations</title><link href="https://rse.shef.ac.uk/blog/2026-01-30-github-organisations/" rel="alternate" type="text/html" title="Managing Research Code at Sheffield: Getting Started with GitHub Organisations" /><published>2026-01-30T12:00:00+00:00</published><updated>2026-01-30T12:00:00+00:00</updated><id>https://rse.shef.ac.uk/blog/2026-01-30-github-organisations</id><content type="html" xml:base="https://rse.shef.ac.uk/blog/2026-01-30-github-organisations/"><![CDATA[<p>This guide is for researchers at the University of Sheffield who need to set up a GitHub Organisation for their team or project. It covers the essential decisions you’ll need to make, explains who is responsible for what, and walks through key security settings.</p>

<h1 id="why-use-a-github-organisation">Why use a GitHub Organisation?</h1>

<p>If you’re already using Git and GitHub for version control (and if you’re not, there are <a href="https://www.software.ac.uk/news/ten-reasons-implement-code-management-practices-early-research-group">good reasons to start</a>), you’ve probably been working from your personal account. That works fine for solo projects, but research groups face a specific problem: what happens to the code when people leave?</p>

<p>When a PhD student or postdoc moves on, their personal repositories often become “gradware”—abandoned code that the group can no longer access or maintain. An Organisation solves this by giving the research group itself ownership of the code, separate from any individual’s account.</p>

<p>Organisations also let you:</p>

<ul>
  <li><strong>Manage access</strong> centrally (who can see what, who can change what)</li>
  <li>Set consistent <strong>security policies</strong> across all your projects</li>
  <li>Keep your group’s <em>*work together</em> in one discoverable place</li>
</ul>

<p>The University’s <a href="https://rse.shef.ac.uk/training/github-enterprise/">GitHub Enterprise Early Access Program</a> provides access to these features. This provides several advantages over a standard free account, including:</p>

<ul>
  <li><strong>Unlimited Private Repositories:</strong> Collaborate securely within your team without public exposure.</li>
  <li><strong>Enhanced Security:</strong> Access to advanced tools like secret scanning to prevent accidental leaks of API keys or credentials.</li>
</ul>

<p><strong>To get started</strong>, you will need to follow the University’s formal onboarding process. Please refer to the <a href="https://rse.shef.ac.uk/training/github-enterprise/">GitHub Enterprise Policy Document</a>; specifically, you will find the required setup form in Section 5 (Requesting an Organisation).</p>

<p><strong>💡 Tip:</strong> When naming your Organisation, choose something descriptive and evergreen such as UoS-[Institute] or UoS-[Lab-Name], rather than something tied to a specific year or project. An organisation can contain multiple repositories that span multiple projects.</p>

<h1 id="who-looks-after-the-organisation"><strong>Who looks after the Organisation?</strong></h1>

<p>GitHub Organisations need designated <strong>Owners</strong>—people who take responsibility for the space. This isn’t just a technical role; it comes with ongoing obligations.</p>

<p><strong>You need at least two owners</strong> for continuity. These people will be responsible for:</p>

<ul>
  <li><strong>User management</strong>: inviting new members, removing people who leave</li>
  <li><strong>Security oversight</strong>: ensuring the organisation follows University policies, responding to security alerts</li>
  <li><strong>Housekeeping</strong>: periodically reviewing inactive members, archiving old repositories</li>
</ul>

<p>Choose your owners carefully. They should be people who’ll be around for a while and who understand (or are willing to learn) the security implications of managing shared code. The full list of owner responsibilities is in Section 1.3 of the <a href="https://rse.shef.ac.uk/training/github-enterprise/">GitHub Enterprise policy</a>.</p>

<p>To prevent an Organisation from becoming “orphaned” when a researcher moves on, we recommend that the Principal Investigator (PI) or a permanent staff member always holds one of the Owner roles. This ensures the department retains access to the research outputs even after students or post-docs finish their contracts.</p>

<h1 id="essential-security-settings"><strong>Essential security settings</strong></h1>

<p>Once your Organisation is created, you’ll need to configure some settings. You’ll find these under <strong>Settings</strong> in your organisation’s GitHub page. The <a href="https://docs.github.com/en/code-security/securing-your-organization">GitHub documentation on security settings</a> covers everything in detail, but here are the key ones to address first.</p>

<p>If you’re working with commercially sensitive code, personal data, or anything requiring particular protection, <a href="https://students.sheffield.ac.uk/it-services/research">contact the Research &amp; Innovation IT team</a> to discuss your specific needs.</p>

<h2 id="restrict-public-repository-creation"><strong>Restrict public repository creation</strong></h2>

<p><strong>Where:</strong> Settings → Member privileges → Repository creation</p>

<p><strong>What to do:</strong> Untick “Public” (leave Private and/or Internal enabled)</p>

<p><strong>Why:</strong> This prevents anyone from accidentally making a repository public. Research code often needs to stay private until publication—or permanently. With this setting, making something public requires deliberate action by an owner.</p>

<h2 id="control-outside-collaborators"><strong>Control outside collaborators</strong></h2>

<p><strong>Where:</strong> Settings → Member privileges → Outside collaborators</p>

<p><strong>What to do:</strong> Untick “Allow repository administrators to invite outside collaborators”</p>

<p><strong>Why:</strong> Outside collaborators are people who aren’t organisation members but can access specific repositories. Without this control, any repository admin could invite external people without oversight. Centralising this with owners means you always know who has access and can ensure external users meet any contractual or ethical requirements.</p>

<h2 id="enable-automated-security-scanning"><strong>Enable automated security scanning</strong></h2>

<p><strong>Where:</strong> Settings → Code security and analysis</p>

<p><strong>What to do:</strong> Enable “Dependabot alerts” and “Secret scanning”</p>

<p><strong>Why:</strong> These tools watch for common security problems:</p>

<ul>
  <li><strong>Dependabot</strong> alerts you when the libraries your code depends on (Python packages, R packages, etc.) have known security vulnerabilities. It can even suggest fixes automatically.</li>
  <li><strong>Secret scanning</strong> catches accidentally committed passwords, API keys, or other credentials. This happens more often than you’d think, and catching it early prevents data breaches.</li>
</ul>

<h2 id="restrict-github-actions"><strong>Restrict GitHub Actions</strong></h2>

<p><strong>Where:</strong> Settings → Actions → General → Policies</p>

<p><strong>What to do:</strong> Select “Allow enterprise actions and reusable workflows”</p>

<p><strong>Why:</strong> GitHub Actions runs automated tasks on your code (tests, checks, deployments). There’s a marketplace of community-built Actions, but not all are trustworthy. Restricting to enterprise-approved actions reduces the risk of malicious code running in your workflows.</p>

<h2 id="limit-personal-access-tokens"><strong>Limit Personal Access Tokens</strong></h2>

<p><strong>Where:</strong> Settings → Personal access tokens → Settings</p>

<p><strong>What to do:</strong> Under “Tokens (classic)”, select “Restrict access via personal access tokens (classic)”</p>

<p><strong>Why:</strong> Personal Access Tokens let scripts access GitHub on behalf of a user. Classic tokens have broad permissions and are a security risk if leaked. This setting forces users to approve which organisations their tokens can access and encourages use of the newer, more secure fine-grained tokens.</p>

<h2 id="require-two-factor-authentication">Require two-factor authentication</h2>

<p><strong>Where:</strong> Settings → Authentication security</p>

<p><strong>What to do:</strong> Tick “Require two-factor authentication for everyone in your organization”</p>

<p><strong>Why:</strong> Your organisation’s security is only as strong as its weakest password. Two-factor authentication means that even if someone’s password is stolen, attackers still can’t access your repositories.</p>

<h1 id="protecting-important-repositories">Protecting important repositories</h1>

<p>Beyond organisation-wide settings, your most important repositories deserve additional protection.</p>

<h2 id="branch-protection-rules"><strong>Branch protection rules</strong></h2>

<p><strong>Where:</strong> Repository Settings → Branches → Add branch protection rule</p>

<p><strong>What to do:</strong> Target your main branch and enable “Require a pull request before merging” and “Require approvals”. While you’re there, also turn on:</p>

<ul>
  <li><strong>Dismiss stale pull request approvals when new commits are pushed</strong></li>
  <li><strong>Require approval of the most recent reviewable push</strong></li>
</ul>

<p><strong>Why:</strong> Without branch protection, anyone on the team—including you—can push changes directly to your main branch. Requiring a pull request means every change has to be reviewed before it lands: the code equivalent of asking a colleague to read over your work before you send it.</p>

<details>
<summary>Why those two extra settings matter</summary>
<p>There is a gap in the default pull request setup that is easy to overlook. Once a PR is approved, any team member can still push new commits to the same branch. The approval stays in place even though the code has changed, so those unreviewed commits can be merged straight through—quietly bypassing the review process.</p>
<p>"Dismiss stale approvals" clears existing sign-offs the moment new commits arrive, forcing another review. "Require approval of the most recent push" goes further: it ensures the reviewer explicitly signed off on exactly what gets merged, not an earlier version of it. Without both settings, the approval requirement is straightforward to circumvent, intentionally or not.</p>
</details>

<h1 id="common-mistakes-to-avoid">Common mistakes to avoid</h1>

<p><strong>Committing data to repositories.</strong> GitHub is for code, not data storage. Large files make repositories sluggish, and committing research data may violate ethics approvals. Use a <code class="language-plaintext highlighter-rouge">.gitignore</code> file to exclude data files and folders.</p>

<p><strong>⚠️ Warning:</strong> GitHub is not a data repository. Never commit raw research data, sensitive participant information, or large binary datasets to GitHub. Use it for code, scripts, and documentation only.</p>

<p><strong>Hard-coding credentials.</strong> It’s tempting to put database passwords or API keys directly in scripts. Don’t. Use environment variables or a <code class="language-plaintext highlighter-rouge">.env</code> file (added to your <code class="language-plaintext highlighter-rouge">.gitignore</code>) to keep credentials separate from code.</p>

<h1 id="going-further">Going further</h1>

<p>This guide covers the essentials, but GitHub offers more for making research software FAIR (Findable, Accessible, Interoperable, Reusable):</p>

<ul>
  <li><strong>Citation files</strong>: Add academic citations using the <a href="https://docs.github.com/en/repositories/managing-your-repositorys-settings-and-features/customizing-your-repository/about-citation-files">Citation File Format</a> so others can credit your work properly</li>
  <li><strong>Archiving with ORDA</strong>: Archive snapshots of your code in the University’s <a href="https://sheffield.ac.uk/library/research-data-management/orda">research data repository</a> with a permanent DOI</li>
  <li><strong>Automated testing</strong>: Use <a href="https://docs.github.com/en/actions">GitHub Actions</a> to run tests automatically when code changes</li>
</ul>

<p>Why use <a href="https://sheffield.ac.uk/library/research-data-management/orda">ORDA</a> instead of just leaving code on GitHub? While GitHub is excellent for active development, it does not guarantee long-term preservation. To meet most funder requirements, you should archive “frozen” versions of your code in ORDA.</p>

<p>Unlike GitHub, ORDA provides a persistent <a href="https://www.doi.org/the-identifier/what-is-a-doi/">Digital Object Identifier (DOI)</a>. This ensures that when you cite your code in a paper, the link will never break, and other researchers can access the exact version of the software used to produce your results.</p>

<p>For more information on integrating GitHub with ORDA (which is based on the FigShare platform,) please read <a href="https://info.figshare.com/user-guide/how-to-connect-figshare-with-your-github-account/">How to connect Figshare with your GitHub account</a> on the FigShare documentation.</p>

<h1 id="summary-checklist">Summary checklist</h1>

<p>If you are starting a new research organisation today, follow these six steps:</p>

<ol>
  <li>Request Access: Complete the form in Section 5 of the Enterprise Policy.</li>
  <li>Assign Owners: Ensure at least two people (including a permanent staff member) have Owner status.</li>
  <li>Restrict Creation: Set “Repository Creation” to Owners Only to prevent sprawl.</li>
  <li>Enforce 2FA: Check that “Require two-factor authentication” is active for all members.</li>
  <li>Protect Branches: Enable “Branch Protection” for your main or master branches.</li>
</ol>

<h1 id="getting-help">Getting help</h1>

<p>Contact the <a href="https://rse.shef.ac.uk/">Research Software Engineering</a> or  <a href="https://students.sheffield.ac.uk/it-services/research">Research &amp; Innovation IT team</a> if you need help choosing the right settings, working with sensitive data, or troubleshooting permissions issues.</p>

<p>While the security configurations outlined above provide a robust baseline for most projects, it is important to remember that security is not a one-size-fits-all requirement. Not every option needs to be strictly locked down in all circumstances; rather, managing an organization involves making informed judgments and balancing security trade-offs against the specific collaborative needs of your research. If you are uncertain about which settings are appropriate for your project’s unique requirements, or if you need help navigating these decisions, you can <a href="https://students.sheffield.ac.uk/it-services/research">contact us</a> for further guidance</p>

<h2 id="training-courses">Training courses</h2>

<p>We offer a range of short courses throughout the year that are free for all researchers. Learn beginner to advanced skills in popular programming languages, computing, and statistical packages.</p>

<p>As part of the <a href="https://rse.shef.ac.uk/training/fair4rs/">FAIR² for research software curriculum</a>, the <a href="https://rse.shef.ac.uk/">Research Software Engineering team</a> provides a two-tiered version control training program tailored specifically for researchers. The journey begins with the “Git, GitHub and GitKraken - From Zero to Hero” module, which introduces absolute beginners to version control basics and collaborative workflows using graphical tools. For those looking to level up, the “Git With It” session dives deeper into branch management, commit history, and advanced collaboration techniques. Together, these modules empower researchers to move beyond basic file saving, ensuring their code is reproducible, organized, and ready for collaborative open research.</p>

<h1 id="online-guidance">Online guidance</h1>

<p>These resources provided by other Universities may be useful as you learn to collaborate on research software using GitHub:</p>

<ul>
  <li><a href="https://www.ucl.ac.uk/advanced-research-computing/expertise/research-software-development/research-software-development-tools/support-ucl-researchers">How to set up GitHub for a research project</a> by University College London</li>
  <li><a href="https://rainsworth.github.io/intro-to-github/">Introduction to Using GitHub</a> by Rachael Ainsworth from the University of Manchester</li>
</ul>]]></content><author><name>Joe Heffer</name></author><category term="github" /><category term="&quot;version" /><category term="control&quot;" /><category term="&quot;github" /><category term="organisations&quot;" /><category term="collaboration" /><category term="security" /><summary type="html"><![CDATA[This guide is for researchers at the University of Sheffield who need to set up a GitHub Organisation for their team or project. It covers the essential decisions you’ll need to make, explains who is responsible for what, and walks through key security settings. Why use a GitHub Organisation? If you’re already using Git and GitHub for version control (and if you’re not, there are good reasons to start), you’ve probably been working from your personal account. That works fine for solo projects, but research groups face a specific problem: what happens to the code when people leave? When a PhD student or postdoc moves on, their personal repositories often become “gradware”—abandoned code that the group can no longer access or maintain. An Organisation solves this by giving the research group itself ownership of the code, separate from any individual’s account. Organisations also let you: Manage access centrally (who can see what, who can change what) Set consistent security policies across all your projects Keep your group’s *work together in one discoverable place The University’s GitHub Enterprise Early Access Program provides access to these features. This provides several advantages over a standard free account, including: Unlimited Private Repositories: Collaborate securely within your team without public exposure. Enhanced Security: Access to advanced tools like secret scanning to prevent accidental leaks of API keys or credentials. To get started, you will need to follow the University’s formal onboarding process. Please refer to the GitHub Enterprise Policy Document; specifically, you will find the required setup form in Section 5 (Requesting an Organisation). 💡 Tip: When naming your Organisation, choose something descriptive and evergreen such as UoS-[Institute] or UoS-[Lab-Name], rather than something tied to a specific year or project. An organisation can contain multiple repositories that span multiple projects. Who looks after the Organisation? GitHub Organisations need designated Owners—people who take responsibility for the space. This isn’t just a technical role; it comes with ongoing obligations. You need at least two owners for continuity. These people will be responsible for: User management: inviting new members, removing people who leave Security oversight: ensuring the organisation follows University policies, responding to security alerts Housekeeping: periodically reviewing inactive members, archiving old repositories Choose your owners carefully. They should be people who’ll be around for a while and who understand (or are willing to learn) the security implications of managing shared code. The full list of owner responsibilities is in Section 1.3 of the GitHub Enterprise policy. To prevent an Organisation from becoming “orphaned” when a researcher moves on, we recommend that the Principal Investigator (PI) or a permanent staff member always holds one of the Owner roles. This ensures the department retains access to the research outputs even after students or post-docs finish their contracts. Essential security settings Once your Organisation is created, you’ll need to configure some settings. You’ll find these under Settings in your organisation’s GitHub page. The GitHub documentation on security settings covers everything in detail, but here are the key ones to address first. If you’re working with commercially sensitive code, personal data, or anything requiring particular protection, contact the Research &amp; Innovation IT team to discuss your specific needs. Restrict public repository creation Where: Settings → Member privileges → Repository creation What to do: Untick “Public” (leave Private and/or Internal enabled) Why: This prevents anyone from accidentally making a repository public. Research code often needs to stay private until publication—or permanently. With this setting, making something public requires deliberate action by an owner. Control outside collaborators Where: Settings → Member privileges → Outside collaborators What to do: Untick “Allow repository administrators to invite outside collaborators” Why: Outside collaborators are people who aren’t organisation members but can access specific repositories. Without this control, any repository admin could invite external people without oversight. Centralising this with owners means you always know who has access and can ensure external users meet any contractual or ethical requirements. Enable automated security scanning Where: Settings → Code security and analysis What to do: Enable “Dependabot alerts” and “Secret scanning” Why: These tools watch for common security problems: Dependabot alerts you when the libraries your code depends on (Python packages, R packages, etc.) have known security vulnerabilities. It can even suggest fixes automatically. Secret scanning catches accidentally committed passwords, API keys, or other credentials. This happens more often than you’d think, and catching it early prevents data breaches. Restrict GitHub Actions Where: Settings → Actions → General → Policies What to do: Select “Allow enterprise actions and reusable workflows” Why: GitHub Actions runs automated tasks on your code (tests, checks, deployments). There’s a marketplace of community-built Actions, but not all are trustworthy. Restricting to enterprise-approved actions reduces the risk of malicious code running in your workflows. Limit Personal Access Tokens Where: Settings → Personal access tokens → Settings What to do: Under “Tokens (classic)”, select “Restrict access via personal access tokens (classic)” Why: Personal Access Tokens let scripts access GitHub on behalf of a user. Classic tokens have broad permissions and are a security risk if leaked. This setting forces users to approve which organisations their tokens can access and encourages use of the newer, more secure fine-grained tokens. Require two-factor authentication Where: Settings → Authentication security What to do: Tick “Require two-factor authentication for everyone in your organization” Why: Your organisation’s security is only as strong as its weakest password. Two-factor authentication means that even if someone’s password is stolen, attackers still can’t access your repositories. Protecting important repositories Beyond organisation-wide settings, your most important repositories deserve additional protection. Branch protection rules Where: Repository Settings → Branches → Add branch protection rule What to do: Target your main branch and enable “Require a pull request before merging” and “Require approvals”. While you’re there, also turn on: Dismiss stale pull request approvals when new commits are pushed Require approval of the most recent reviewable push Why: Without branch protection, anyone on the team—including you—can push changes directly to your main branch. Requiring a pull request means every change has to be reviewed before it lands: the code equivalent of asking a colleague to read over your work before you send it. Why those two extra settings matter There is a gap in the default pull request setup that is easy to overlook. Once a PR is approved, any team member can still push new commits to the same branch. The approval stays in place even though the code has changed, so those unreviewed commits can be merged straight through—quietly bypassing the review process. "Dismiss stale approvals" clears existing sign-offs the moment new commits arrive, forcing another review. "Require approval of the most recent push" goes further: it ensures the reviewer explicitly signed off on exactly what gets merged, not an earlier version of it. Without both settings, the approval requirement is straightforward to circumvent, intentionally or not. Common mistakes to avoid Committing data to repositories. GitHub is for code, not data storage. Large files make repositories sluggish, and committing research data may violate ethics approvals. Use a .gitignore file to exclude data files and folders. ⚠️ Warning: GitHub is not a data repository. Never commit raw research data, sensitive participant information, or large binary datasets to GitHub. Use it for code, scripts, and documentation only. Hard-coding credentials. It’s tempting to put database passwords or API keys directly in scripts. Don’t. Use environment variables or a .env file (added to your .gitignore) to keep credentials separate from code. Going further This guide covers the essentials, but GitHub offers more for making research software FAIR (Findable, Accessible, Interoperable, Reusable): Citation files: Add academic citations using the Citation File Format so others can credit your work properly Archiving with ORDA: Archive snapshots of your code in the University’s research data repository with a permanent DOI Automated testing: Use GitHub Actions to run tests automatically when code changes Why use ORDA instead of just leaving code on GitHub? While GitHub is excellent for active development, it does not guarantee long-term preservation. To meet most funder requirements, you should archive “frozen” versions of your code in ORDA. Unlike GitHub, ORDA provides a persistent Digital Object Identifier (DOI). This ensures that when you cite your code in a paper, the link will never break, and other researchers can access the exact version of the software used to produce your results. For more information on integrating GitHub with ORDA (which is based on the FigShare platform,) please read How to connect Figshare with your GitHub account on the FigShare documentation. Summary checklist If you are starting a new research organisation today, follow these six steps: Request Access: Complete the form in Section 5 of the Enterprise Policy. Assign Owners: Ensure at least two people (including a permanent staff member) have Owner status. Restrict Creation: Set “Repository Creation” to Owners Only to prevent sprawl. Enforce 2FA: Check that “Require two-factor authentication” is active for all members. Protect Branches: Enable “Branch Protection” for your main or master branches. Getting help Contact the Research Software Engineering or Research &amp; Innovation IT team if you need help choosing the right settings, working with sensitive data, or troubleshooting permissions issues. While the security configurations outlined above provide a robust baseline for most projects, it is important to remember that security is not a one-size-fits-all requirement. Not every option needs to be strictly locked down in all circumstances; rather, managing an organization involves making informed judgments and balancing security trade-offs against the specific collaborative needs of your research. If you are uncertain about which settings are appropriate for your project’s unique requirements, or if you need help navigating these decisions, you can contact us for further guidance Training courses We offer a range of short courses throughout the year that are free for all researchers. Learn beginner to advanced skills in popular programming languages, computing, and statistical packages. As part of the FAIR² for research software curriculum, the Research Software Engineering team provides a two-tiered version control training program tailored specifically for researchers. The journey begins with the “Git, GitHub and GitKraken - From Zero to Hero” module, which introduces absolute beginners to version control basics and collaborative workflows using graphical tools. For those looking to level up, the “Git With It” session dives deeper into branch management, commit history, and advanced collaboration techniques. Together, these modules empower researchers to move beyond basic file saving, ensuring their code is reproducible, organized, and ready for collaborative open research. Online guidance These resources provided by other Universities may be useful as you learn to collaborate on research software using GitHub: How to set up GitHub for a research project by University College London Introduction to Using GitHub by Rachael Ainsworth from the University of Manchester]]></summary></entry><entry><title type="html">RSE Supported Projects</title><link href="https://rse.shef.ac.uk/blog/2025-09-30-funded-proposals/" rel="alternate" type="text/html" title="RSE Supported Projects" /><published>2025-09-30T13:00:00+01:00</published><updated>2025-09-30T13:00:00+01:00</updated><id>https://rse.shef.ac.uk/blog/2025-09-30-funded-proposals</id><content type="html" xml:base="https://rse.shef.ac.uk/blog/2025-09-30-funded-proposals/"><![CDATA[<p>Following the success of the <a href="2024-09-24-funded-proposals">2024 call for proposals</a> the RSE team in Sheffield put a call
out a second call for proposals earlier this year. The call was open to all researchers across the university and
successful applicants would receive dedicated support from an RSE Team member for upto 50% FTE for a period of six
months.</p>

<p>Here we review the work undertaken on the projects we supported last year and introduce the successful applications in
the 2025 round.</p>

<!--more-->

<h2 id="2025-call-for-proposals">2025 Call for Proposals</h2>

<p>This year saw an increase in the number of applications with 35 received by the deadline, an increase from the 26
applications received in 2024. A review panel of ten RSEs from the RSE team and adjacent Data Analytics Service was
convened to assess the applications and decide which should receive support. The panel enjoyed reviewing the diverse
applications and had a challenging decisions to make as to which projects to support as the quality of applications was
again high.</p>

<p><img src="/assets/images/2025-09-30-funded-proposals-faculty.png" alt="Distribution of applications by faculty" title="Bar chart showing the distribution
of applications by faculty. Engineering had 14 applications, Science 10, Social Sciences 4, Health 6 and 1 applicaiton
from AMRC" /></p>

<p>All work undertaken will be done with a view to adhering to the <a href="https://rse.shef.ac.uk/training/fair4rs/">FAIR for Research Software Principles</a></p>

<h3 id="optimising--efficiency-improvement-of-a-national-building-material-stock">Optimising &amp; Efficiency Improvement of a National Building Material Stock</h3>

<p><a href="https://sheffield.ac.uk/mac/people/civil-academic-staff/danielle-densley-tingley">Professor Danielle Densley Tingley</a>’s research “<em>explores sustainable building design solutions, focusing on
material impacts, so we can create a built environment that operates within the carrying capacity of the planet.</em>”. To
achieve this they are developing models of existing building stock using a hierarchical building material intensity
(HMI) framework to assess what buildings are made of in the UK. The software is implemented in Python and has been
applied to building stock in suburbs of London but the group is looking to extend its application to the rest of the
UK. The proposed work will profile the existing code base with a view to optimising its performance, review the existing
database structures with a view to improving efficiencies and implement parallelisation so that analyses can scale and
leverage High Performance Computing (HPC) facilities that are available to researchers.</p>

<h3 id="yorkshire-and-humber-office-for-data-analytics-yohda">Yorkshire and Humber Office for Data Analytics (YOHDA)</h3>

<p><a href="https://sheffield.ac.uk/management/people/academic-staff/esib/vania-sena">Professor Vania Sena</a> from the University’s Management School submitted this proposal to improve the code base
that underpins <a href="https://yhoda.sites.sheffield.ac.uk">YOHDA</a> a data resources that “<em>supports data-drive decision making through open-access data and
analytics</em>” that pulls open data from resources such as the Office for National Statistics (ONS), Department for Work
and Pensions (DWP) and many others. Currently the aggregation of data is a manual process that is limiting the
scalability of the project. RSE support will develop a structured SQL database server that uses Advanced Programming
Interfaces (APIs) to automate the data ingress and optimise the existing transformation and cleaning routines to improve
performance and stability, streamlining the workflow and reducing the overhead of maintaining this valuable resource.
At the same time documentation will be developed that facilitates on-boarding and aids in up-skilling of team members.</p>

<h3 id="software-for-modelling-neutrino-emission-from-spent-nuclear-fuel">Software for Modelling Neutrino Emission from Spent Nuclear Fuel</h3>

<p>Spent Nuclear Fuel is stored in above-ground dry casks at interim storage facilities, where it is monitored for
decades for safety and nonproliferation. Effective monitoring technologies are of great importance, as interim
facilities store hundreds of tonnes of highly radioactive spent fuel, and increasing reliance on civil nuclear power has
led to more interest in developing improved methods of monitoring SNF. <a href="https://sheffield.ac.uk/mps/people/research-staff/liz-kneale">Dr Elisabeth Kneale</a> has developed
Python software package predict antineutrino emission spectrum from Spent Nuclear Fuel but has sought the assistance of
the RSE team to improve the open-source nature of the software, packaging, develop a Graphical User Interface (GUI)
whilst improving compliance with the <a href="https://rse.shef.ac.uk/training/fair4rs/">FAIR4RS</a> standards.</p>

<h2 id="conclusion">Conclusion</h2>

<p>The call for proposals in 2025 has again shown there is a diverse need for RSE support across all departments of the
University of Sheffield and that increasingly researchers are recognising the benefits that dedicated RSE support can
bring to the software components of academic research. The RSE team are pleased to be able to support researchers the
successful applicants to this years call.</p>

<p>If you are considering putting in a funding application that involves writing/developing/maintaining software
having dedicated RSE support can strengthen your proposal. If you would like to speak to the RSE team about support
please don’t hesitate to get in touch by emailing <a href="mailto:rse@sheffield.ac.uk">rse@sheffield.ac.uk</a>.</p>]]></content><author><name>Neil Shephard</name></author><category term="rse" /><category term="&quot;call" /><category term="for" /><category term="proposals&quot;" /><category term="support" /><summary type="html"><![CDATA[Following the success of the 2024 call for proposals the RSE team in Sheffield put a call out a second call for proposals earlier this year. The call was open to all researchers across the university and successful applicants would receive dedicated support from an RSE Team member for upto 50% FTE for a period of six months. Here we review the work undertaken on the projects we supported last year and introduce the successful applications in the 2025 round.]]></summary></entry><entry><title type="html">Sheffield RSE travelled to RSECon25</title><link href="https://rse.shef.ac.uk/blog/2025-09-29-rsecon25/" rel="alternate" type="text/html" title="Sheffield RSE travelled to RSECon25" /><published>2025-09-29T13:00:00+01:00</published><updated>2025-09-29T13:00:00+01:00</updated><id>https://rse.shef.ac.uk/blog/2025-09-29-rsecon25</id><content type="html" xml:base="https://rse.shef.ac.uk/blog/2025-09-29-rsecon25/"><![CDATA[<p>A few weeks ago, the Research Software Engineering (RSE) community gathered at the University of Warwick 
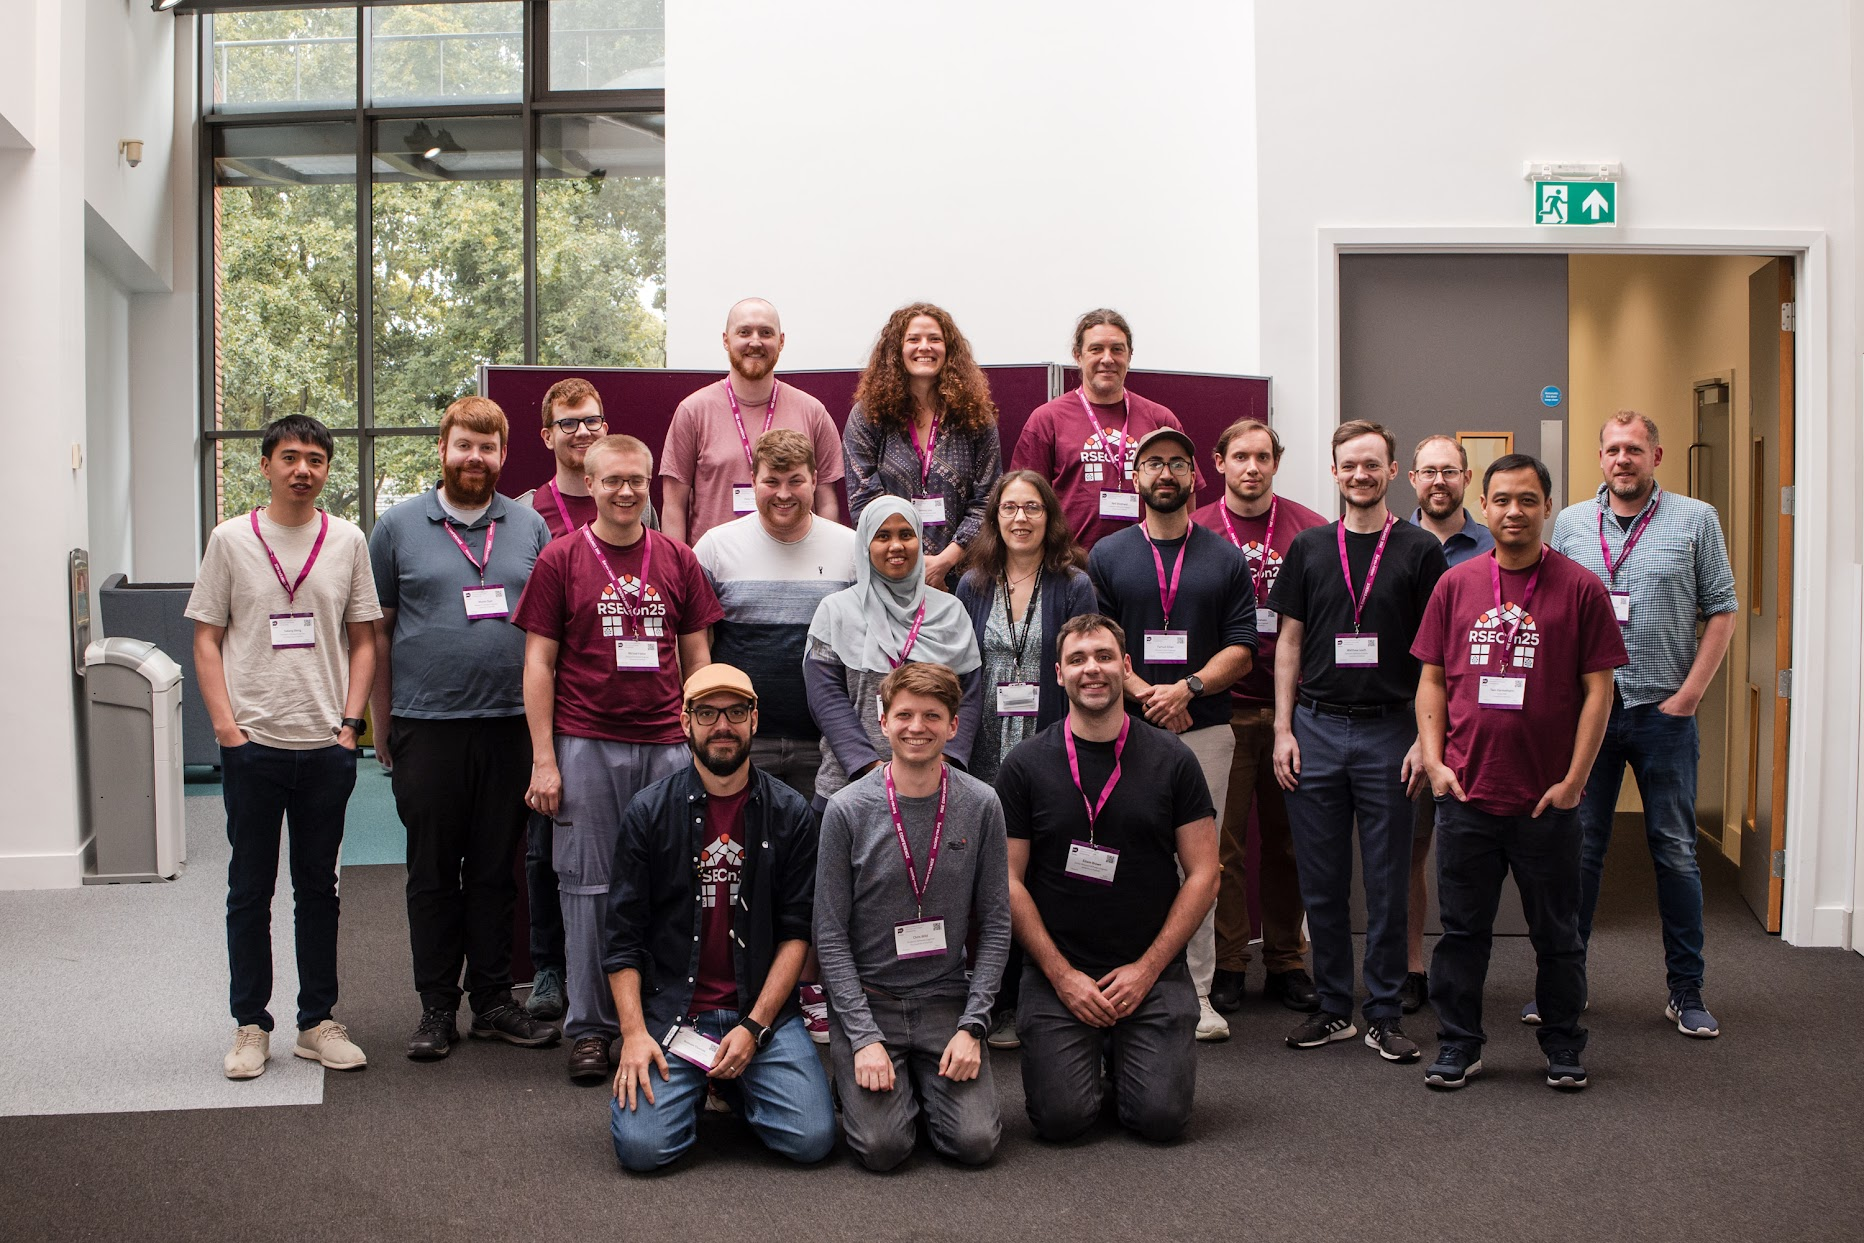
for <a href="https://rsecon25.society-rse.org/">RSECon25</a> (9–11 September 2025). The conference brought together hundreds of RSEs, researchers, 
and collaborators to share their work on software, best practices, exchange ideas, and build the future of research software.</p>

<table>
  <thead>
    <tr>
      <th style="text-align: center"><img src="/assets/images/2025-09-29-RSECon25.png" alt="Sheffield representation at RSECon25" /></th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: center">From left to right: Yuliang Weng, Martin Dyer, Daniel Brady, Michael Foster, Romain Thomas, Peter Heywood, Shaun Donnelly, Erika Siregar (PhD from the information School), Christopher Wild, Gemma Ives, Tamora James, Edwin Brown, Neil Shephard, Farhad Allian, Robert Chisholm,Matthew Leach, Joe Heffer, Twin Karmakharm, Paul Richmond</td>
    </tr>
  </tbody>
</table>

<p>The University of Sheffield RSEs played a <strong>major role</strong> in this year’s event — not only as 
a <strong><a href="https://rsecon25.society-rse.org/sponsors/">Silver Sponsor</a></strong>, but also through leadership positions, presentations, posters, workshops, and volunteering. Our team’s involvement demonstrates Sheffield’s strong commitment to the RSE community.</p>

<p>Several Sheffield RSEs took on <strong>key leadership roles</strong> in shaping RSECon25:</p>

<ul>
  <li><strong>Twin Karmakharm</strong> – Steering Committee Chair</li>
  <li><strong>Romain Thomas</strong> – Programme Co-chair</li>
  <li><strong>Robert Chisholm</strong> – Logistics Co-chair</li>
  <li><strong>Neil Shephard</strong> – Publicity Chair</li>
</ul>

<p>These roles highlight the influence and responsibility our team have in driving the direction and success of the national RSE conference.</p>

<p>In addition, Sheffield’s RSE team was present across the programme, with contributions spanning talks, posters, walkthroughs, and workshops:</p>

<ul>
  <li><strong>Talks</strong> &amp; Walkthrough:
    <ul>
      <li><strong>Matthew Leach</strong> – AMD GPUs for Scientific Computing</li>
      <li><strong>Shaun Donnelly</strong> <strong>&amp; Edwin Brown</strong> – How to talk to your documents: An introduction to using natural language to query documents with Retrieval Augmented Generation (RAG)</li>
      <li><strong>Romain Thomas</strong> &amp; <strong>Neil Shephard</strong>  – Running a local RSE call for proposals</li>
    </ul>
  </li>
  <li><strong>Workshops</strong>:
    <ul>
      <li><strong>Robert Chisholm</strong> &amp; <strong>Peter Heywood</strong>  – Reasonable Performance Computing SIG (SIG-RPC): Help Identify and Document Performance Traps in Research Software</li>
    </ul>
  </li>
  <li><strong>Posters</strong>:
    <ul>
      <li><strong>Tamora James</strong> <strong>&amp; Romain Thomas</strong> - FAIR2 for research software: developing a FAIR (Findable, Accessible, Interoperable and Reusable) and reproducible research software training programme</li>
      <li><strong>Edwin Brown</strong> - AutoEmulate:  Python library for automatically creating accurate and efficient emulators of complex simulations</li>
      <li><strong>Dan Brady</strong> - Leveraging GitHub API Data to Evaluate Git and GitHub Training Outcomes</li>
      <li><strong>Martin Dyer</strong> - Developing the GOTO Telescope Control System</li>
    </ul>
  </li>
</ul>

<p>This broad and diverse participation reflects the strength of our team across technical expertise, training, and community support.</p>

<p>Sheffield colleagues also supported the smooth running of the conference through volunteering (Daniel Brady &amp; Michael Foster) and session chairing (Paul Richmond &amp; Joe Heffer from the DAS team).</p>

<h2 id="looking-towards-rsecon26">Looking towards RSECon26</h2>

<p>We are excited to announce that the <strong>University of Sheffield will host RSECon26 in 2026 at the wave</strong> (9-11th September), which will also be co-located with the first <a href="https://www.researchsoft.org/irsc/">International Research Software Conference (IRSC)</a> (7-8th September). 
Building on our contributions at Warwick, we look forward to welcoming the RSE community to Sheffield next year for another vibrant and impactful conference. Romain Thomas and Twin Karmakharm will be leading the conference as programme chairs.</p>

<ul>
  <li>Credit Photo: RSE Society</li>
</ul>]]></content><author><name>Romain Thomas</name></author><category term="rse" /><category term="conference" /><summary type="html"><![CDATA[A few weeks ago, the Research Software Engineering (RSE) community gathered at the University of Warwick for RSECon25 (9–11 September 2025). The conference brought together hundreds of RSEs, researchers, and collaborators to share their work on software, best practices, exchange ideas, and build the future of research software. From left to right: Yuliang Weng, Martin Dyer, Daniel Brady, Michael Foster, Romain Thomas, Peter Heywood, Shaun Donnelly, Erika Siregar (PhD from the information School), Christopher Wild, Gemma Ives, Tamora James, Edwin Brown, Neil Shephard, Farhad Allian, Robert Chisholm,Matthew Leach, Joe Heffer, Twin Karmakharm, Paul Richmond The University of Sheffield RSEs played a major role in this year’s event — not only as a Silver Sponsor, but also through leadership positions, presentations, posters, workshops, and volunteering. Our team’s involvement demonstrates Sheffield’s strong commitment to the RSE community. Several Sheffield RSEs took on key leadership roles in shaping RSECon25: Twin Karmakharm – Steering Committee Chair Romain Thomas – Programme Co-chair Robert Chisholm – Logistics Co-chair Neil Shephard – Publicity Chair These roles highlight the influence and responsibility our team have in driving the direction and success of the national RSE conference. In addition, Sheffield’s RSE team was present across the programme, with contributions spanning talks, posters, walkthroughs, and workshops: Talks &amp; Walkthrough: Matthew Leach – AMD GPUs for Scientific Computing Shaun Donnelly &amp; Edwin Brown – How to talk to your documents: An introduction to using natural language to query documents with Retrieval Augmented Generation (RAG) Romain Thomas &amp; Neil Shephard – Running a local RSE call for proposals Workshops: Robert Chisholm &amp; Peter Heywood – Reasonable Performance Computing SIG (SIG-RPC): Help Identify and Document Performance Traps in Research Software Posters: Tamora James &amp; Romain Thomas - FAIR2 for research software: developing a FAIR (Findable, Accessible, Interoperable and Reusable) and reproducible research software training programme Edwin Brown - AutoEmulate:  Python library for automatically creating accurate and efficient emulators of complex simulations Dan Brady - Leveraging GitHub API Data to Evaluate Git and GitHub Training Outcomes Martin Dyer - Developing the GOTO Telescope Control System This broad and diverse participation reflects the strength of our team across technical expertise, training, and community support. Sheffield colleagues also supported the smooth running of the conference through volunteering (Daniel Brady &amp; Michael Foster) and session chairing (Paul Richmond &amp; Joe Heffer from the DAS team). Looking towards RSECon26 We are excited to announce that the University of Sheffield will host RSECon26 in 2026 at the wave (9-11th September), which will also be co-located with the first International Research Software Conference (IRSC) (7-8th September). Building on our contributions at Warwick, we look forward to welcoming the RSE community to Sheffield next year for another vibrant and impactful conference. Romain Thomas and Twin Karmakharm will be leading the conference as programme chairs. Credit Photo: RSE Society]]></summary></entry><entry><title type="html">RSE Supported Projects</title><link href="https://rse.shef.ac.uk/blog/2024-09-24-funded-proposals/" rel="alternate" type="text/html" title="RSE Supported Projects" /><published>2024-09-24T13:00:00+01:00</published><updated>2024-09-24T13:00:00+01:00</updated><id>https://rse.shef.ac.uk/blog/2024-09-24-funded-proposals</id><content type="html" xml:base="https://rse.shef.ac.uk/blog/2024-09-24-funded-proposals/"><![CDATA[<p>Earlier this year the RSE team in Sheffield put a call out for proposals for researchers in the University of Sheffield to
<a href="https://rse.shef.ac.uk/collaboration/RSEtime_call2024/">collaborate with the RSE</a> team. The successful applicants would receive dedicated support from an RSE
Team member at 50% FTE for a period of six months.</p>

<!--more-->

<p>A total of 26 applications were received from across the faculties of the University and the review panel which
consisted of nine RSEs had robust discussions about which to fund as the quality and proposed work was of a high
standard.</p>

<p><img src="/assets/images/2024-09-24-funded-proposals-faculty.png" alt="Distribution of applications by faculty" /></p>

<p>In the end the RSE team was able to fund support for three proposals and team members <a href="https://rse.shef.ac.uk/contact/robert-chisholm/">Dr Robert Chisholm</a> and <a href="https://rse.shef.ac.uk/contact/neil-shephard/">Neil
Shephard</a> are about to start work on two of the projects with the third postponed, with agreement, until a new RSE
who has been recruited starts later in the year.</p>

<p>All work undertaken will be done with a view to adhering to the <a href="https://rse.shef.ac.uk/training/fair4rs/">FAIR for Research Software Principles</a></p>

<h2 id="slamseq">SLAMSeq</h2>

<p>The <a href="https://www.sudlab.co.uk/team-1/ian-sudbery">SubLab</a>, which is lead by <a href="https://www.sheffield.ac.uk/biosciences/academic-staff/people/ian-sudbery">Dr Ian Subery</a>, have developed software to analyse the output of SLAMSeq
experiments which performs sequence alignment of variably spliced RNA sequences to assess degradation rates. Despite
wide adoption of the technique the current software is limited to only being run on a per-gene basis rather than per
isoform basis and statistical comparison of differences in decay rates are limited. The <a href="https://www.sudlab.co.uk/team-1/ian-sudbery">Sudlab</a> have addressed
this deficiency by developing an analysis pipeline with pre-processing performed in Python and statistical analysis
undertaken in R.</p>

<p>RSE support will be used to refactor the code into formal packages with a modular code structure and formal tests which
facilitate long-term maintenance and make extension easier and will make it straight-forward for users to
install. Translation of code into a single language will be considered as this would lower the barrier to uptake by
external users and documentation will be developed and deployed covering the API and the practical side of using the
software.</p>

<h2 id="hybird">HYBIRD</h2>

<p><a href="https://github.com/gnomeCreative/HYBIRD">HYBIRD</a> is software developed by <a href="https://www.sheffield.ac.uk/mac/people/civil-academic-staff/alessandro-leonardi">Dr Alessandro Leonardi</a> and his research group with the
Geo-Technical Engineering group and is written using C++. It combines the Discrete Element Method (DEM) and the Lattice
Boltzmann Method (LBM) to simulate complex particle-fluid interactions. These fluid-structure interactions have
allowed the investigation of the formation of granular fronts in free-surface flows, enhancing understanding of
particle-laden flow dynamics which have been successfully applied to key areas in environmental and geo-technical
engineering.</p>

<p>Work will be undertaken by <a href="https://rse.shef.ac.uk/contact/robert-chisholm/">Dr Robert Chisholm</a>, a performance optimisation and GPU parallelisation specialist from
our team, to modernise HYBIRD’s build system, address the limiting factors of its performance and enable it to take
advantage of GPU parallelisation. The broad objectives of this project are to reduce barriers to entry for new users and
to increase the performance to enable faster and larger research experiments.</p>

<h2 id="polychron">Polychron</h2>

<p><a href="https://github.com/bryonymoody/PolyChron">Polychron</a> is prototype software developed by <a href="https://www.sheffield.ac.uk/mps/people/all-academic-staff/bryony-moody">Dr Bryony Moody</a> of the School of Mathematical and
Physical Sciences that facilitates the analysis and archiving of archaeological dating evidence. Written in Python the
prototype consists of a statistical algorithm (backend) and a GUI frontend to facilitate usage.</p>

<p>Work will be undertaken by a new RSE who will be starting later in the year. The exact remit of the work to be
undertaken has not yet been finalised but the code base will benefit from restructuring into a Python package with
refactoring of the GUI to make it easier to maintain and extend and improved error detection.</p>

<h2 id="summary">Summary</h2>

<p>As the number of applications demonstrated, the demand for RSE support across all faculties within the University is
high and it was interesting to find out about the broad range of software projects being undertaken by different
research groups. We wish we could have supported more of these teams.</p>

<p>If you are considering putting in a funding application that involves writing/developing/maintaining software
having dedicated RSE support can strengthen your proposal. If you would like to speak to the RSE team about support
please don’t hesitate to get in touch by emailing <a href="mailto:rse@sheffield.ac.uk">rse@sheffield.ac.uk</a>.</p>]]></content><author><name>Neil Shephard</name></author><category term="rse" /><category term="&quot;call" /><category term="for" /><category term="proposals&quot;" /><category term="support" /><summary type="html"><![CDATA[Earlier this year the RSE team in Sheffield put a call out for proposals for researchers in the University of Sheffield to collaborate with the RSE team. The successful applicants would receive dedicated support from an RSE Team member at 50% FTE for a period of six months.]]></summary></entry><entry><title type="html">Python Virtualenvwrapper</title><link href="https://rse.shef.ac.uk/blog/2024-08-13-python-virtualenvwrapper/" rel="alternate" type="text/html" title="Python Virtualenvwrapper" /><published>2024-08-13T13:00:00+01:00</published><updated>2024-08-13T13:00:00+01:00</updated><id>https://rse.shef.ac.uk/blog/2024-08-13-python-virtualenvwrapper</id><content type="html" xml:base="https://rse.shef.ac.uk/blog/2024-08-13-python-virtualenvwrapper/"><![CDATA[<p>This article introduces  <a href="https://virtualenvwrapper.readthedocs.io/en/latest/">virtualenvwrapper</a> for creating and
working with <a href="https://www.python/org">Python</a> Virtual Environments showing how to install and use it and highlighting
some useful features.</p>

<!--more-->

<div style="width: 80%; margin:0 auto;"><img src="https://live.staticflickr.com/65535/53176160657_1a148b3c36_k.jpg" alt="Clouds Rising at Sunset in the Julian Alps" /><p>Photo by <a href="https://www.flickr.com/photos/slackline/53176160657/" target="_blank">Neil Shephard</a>.</p></div>

<p>If you use <a href="https://www.python/org">Python</a> regularly chances are you are familiar with and use virtual environments to
isolate the installed packages as you develop your code from the Python packages installed at the system level. The
standard library <a href="https://docs.python.org/3/library/venv.html">venv</a>, and other packages such as
<a href="https://github.com/pypa/pipx">pipx</a>, <a href="https://virtualenv.pypa.io/en/latest/">virtualenv</a> and
<a href="https://www.anaconda.com/">Anaconda</a> are all popular options. Many of the popular package development suites such as
<a href="https://hatch.pypa.io/latest/">Hatch</a>, <a href="https://pdm-project.org/latest/">PDM</a> and <a href="https://python-poetry.org/">Poetry</a>
will also manage virtual environments for you too. One you might not have come across is
<a href="https://virtualenvwrapper.readthedocs.io/en/latest/">virtualenvwrapper</a> which is…</p>

<blockquote>
  <p><em>a set of extensions to Ian Bicking’s virtualenv tool. The extensions include wrappers for creating and deleting
virtual environments and otherwise managing your development workflow, making it easier to work on more than one
project at a time without introducing conflicts in their dependencies.</em></p>
</blockquote>

<p><strong>NB</strong> If you are using Microsoft Windows you can follow along by using <a href="https://learn.microsoft.com/en-us/windows/wsl/install">Windows Subsystem for
Linux</a>, otherwise <code class="language-plaintext highlighter-rouge">virtualenvwrapper</code> installation and usage is
slightly different under Windows and you should consult the
<a href="https://virtualenvwrapper.readthedocs.io/en/latest/">virtualenvwrapper</a>.</p>

<h2 id="what-are-virtual-environments">What are Virtual Environments?</h2>

<p>Before getting started a quick recap for readers who aren’t familiar with virtual environments.</p>

<p>When you run programmes, such as invoking <code class="language-plaintext highlighter-rouge">python</code> at the command line, whether that is GNU/Linux, Mac OSX or Microsoft
Windows, the operating system searches for the command you run in a defined set of places. It doesn’t look everywhere,
rather it looks in the locations defined by an environment variable called <code class="language-plaintext highlighter-rouge">$PATH</code>. This variable holds a set of
paths to locations in which to look for executable/binary programmes. You can inspect its value with <code class="language-plaintext highlighter-rouge">echo $PATH</code>. The
order in which the listed paths are checked takes left-to-right precedence and on my system this looks like the following.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>❱ <span class="nb">echo</span> <span class="nv">$PATH</span>
/home/neil/.local/share/pnpm:/home/neil/bin:/home/neil/.cargo/bin:/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin:/opt/bin:/usr/lib/llvm/18/bin:/usr/lib/llvm/17/bin:/home/neil/.local/bin:/home/neil/.cargo/bin:/home/neil/.node/bin
</code></pre></div></div>

<p>Thus if I invoke <code class="language-plaintext highlighter-rouge">python</code> the first path that is checked for a binary with that name is <code class="language-plaintext highlighter-rouge">/home/neil/.local/share/pnpm</code>.
If one isn’t found the second is checked (<code class="language-plaintext highlighter-rouge">/home/neil/bin</code>), then the third (<code class="language-plaintext highlighter-rouge">/home/neil/.cargo/bin</code>) and so on until a
match is found. If no match is found you can check the path to a given binary using <code class="language-plaintext highlighter-rouge">which</code> and if no programme with
that name is found you are told. This means its either not installed o your system or you perhaps made a tpyo (<strong>Hint</strong>
use <a href="https://www.cyberciti.biz/faq/add-bash-auto-completion-in-ubuntu-linux/">tab-complete</a> its usually installed and
works in most shells).</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>❱ which python
/usr/bin/python
❱ which ptyhon
ptyhon not found
</code></pre></div></div>

<p>A virtual environment modifies the <code class="language-plaintext highlighter-rouge">$PATH</code> variable, placing a new path at the start that points to a directory under
your user account that contains a copy of <code class="language-plaintext highlighter-rouge">python</code> and the specific set of packages you have installed under that
environment. We’ll cover this in more detail but if I look at the <code class="language-plaintext highlighter-rouge">$PATH</code> variable <em>after</em> having activated the
<code class="language-plaintext highlighter-rouge">topostats</code> virtual environment you will see that its value has been modified and the <em>first</em> directory that is checked
is <code class="language-plaintext highlighter-rouge">/home/neil/.virtualenvs/topostats/bin</code> and if I check which version of <code class="language-plaintext highlighter-rouge">python</code> is used it is the one within this
directory.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>❱ <span class="nb">echo</span> <span class="nv">$PATH</span>
/home/neil/.virtualenvs/topostats/bin:/home/neil/.local/share/pnpm:/home/neil/miniconda3/condabin:/home/neil/bin:/home/neil/.cargo/bin:/usr/local/sbin:/usr/local/bin:/usr/sbin:/usr/bin:/sbin:/bin:/opt/bin:/usr/lib/llvm/18/bin:/usr/lib/llvm/17/bin:/home/neil/.local/bin:/home/neil/.cargo/bin:/home/neil/.node/bin
❱ which python
/home/neil/.virtualenvs/topostats/bin/python
</code></pre></div></div>

<h2 id="managing-virtual-environments-with-virtualenvwrapper">Managing Virtual Environments with <code class="language-plaintext highlighter-rouge">virtualenvwrapper</code></h2>

<p>As the name suggests <a href="https://virtualenvwrapper.readthedocs.io/en/latest/"><code class="language-plaintext highlighter-rouge">virtualenvwrapper</code></a> is a wrapper for the
<a href="https://virtualenv.pypa.io/en/latest/"><code class="language-plaintext highlighter-rouge">virtualenv</code></a> package that adds a bunch of convenience functions and features
that, in this author’s view, make it easier to install, activate/deactivate and manage your virtual environments.</p>

<h3 id="installation">Installation</h3>

<p>I recommend installing <code class="language-plaintext highlighter-rouge">virtualenvwrapper</code> at the system level, ideally with your systems package manager. Under
different GNU/Linux or OSX using Homebrew this can be done with…</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>❱ <span class="nb">sudo </span>pacman <span class="nt">-Syu</span> virtualenvwrapper       <span class="c"># Arch</span>
❱ <span class="nb">sudo </span>emerge <span class="nt">-av</span> virtualenvwrapper        <span class="c"># Gentoo</span>
❱ <span class="nb">sudo </span>apt-get <span class="nb">install </span>virtualenvwrapper   <span class="c"># Debian/Ubuntu</span>
❱ brew <span class="nb">install </span>virtualenvwrapper           <span class="c"># OSX Homebrew</span>
</code></pre></div></div>

<p>…or if you are happy installing packages using <code class="language-plaintext highlighter-rouge">pip</code> you can follow the <a href="https://virtualenvwrapper.readthedocs.io/en/latest/install.html">official installation
instructions</a> and use <code class="language-plaintext highlighter-rouge">pip</code> to install at the system
level.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>❱ <span class="nb">sudo </span>pip <span class="nb">install </span>virtualenvwrapper
</code></pre></div></div>

<p>Alternatively you can install locally using <code class="language-plaintext highlighter-rouge">pip</code> by using the <code class="language-plaintext highlighter-rouge">--user</code> flag.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>❱ pip <span class="nb">install</span> <span class="nt">--user</span> virtualenvwrapper
</code></pre></div></div>

<p>You now need to ensure that the <code class="language-plaintext highlighter-rouge">virtualenvwrapper.sh</code> is sourced each time you start a new shell. To do this you need
to add lines similar to the following to your <code class="language-plaintext highlighter-rouge">~/.bashrc</code> or <code class="language-plaintext highlighter-rouge">~/.zshrc</code> files depending on which shell you use (the
former is the default on most GNU/Linux systems and Windows Subsystem for Linux, the later is the default under OSX).</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c"># Configure and setup virtualenvwrapper</span>
<span class="nb">export </span><span class="nv">WORKON_HOME</span><span class="o">=</span><span class="k">${</span><span class="nv">HOME</span><span class="k">}</span>/.virtualenvs
<span class="nb">export </span><span class="nv">PROJECT_HOME</span><span class="o">=</span><span class="k">${</span><span class="nv">HOME</span><span class="k">}</span>/work/
<span class="nb">source</span> /usr/local/bin/virtualenvwrapper.sh
</code></pre></div></div>

<p>The values of <code class="language-plaintext highlighter-rouge">PROJECT_HOME</code> should be specific to where you wish to create your projects, whilst the argument to
<code class="language-plaintext highlighter-rouge">source</code> will depend on how you have installed <code class="language-plaintext highlighter-rouge">virtualenvwrapper</code>, you can check using <code class="language-plaintext highlighter-rouge">which</code> so use the value
returned by</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>❱ which virtualenvwrapper.sh
/usr/bin/virtualenvwrapper.sh
</code></pre></div></div>

<h3 id="always-using-a-virtual-environment">Always using a virtual environment</h3>

<p>Once in <code class="language-plaintext highlighter-rouge">virtualenvwrapper</code> is installed you can change a configuration option to <code class="language-plaintext highlighter-rouge">pip</code> to ensure that you are <em>always</em>
using a virtual environment when you attempt to install packages using <code class="language-plaintext highlighter-rouge">pip</code> by adding the following to the
<code class="language-plaintext highlighter-rouge">~/.config/pip/pip.conf</code> file on your system.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">[</span>global]
require-virtualenv <span class="o">=</span> True
</code></pre></div></div>

<h2 id="creating-a-virtual-environment-with-virtualenvwrapper">Creating a Virtual Environment with <code class="language-plaintext highlighter-rouge">virtualenvwrapper</code></h2>

<p>This is straight-forward.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>❱ mkvirtualenv test_env
<span class="o">(</span>test_env<span class="o">)</span> ❱
</code></pre></div></div>

<p>By default on creating a new virtual environment it is activated and your prompt should change to reflect this with the
environment name appearing as part of the prompt. You can check that the <code class="language-plaintext highlighter-rouge">python</code> that will be executed resides in this
directory using <code class="language-plaintext highlighter-rouge">which</code>.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">(</span>test_env<span class="o">)</span> ❱ which python
/home/neil/.virtualenvs/test_env/bin/python
</code></pre></div></div>

<h2 id="activatingdeactivating-virtual-environment">Activating/Deactivating Virtual Environment</h2>

<p>You have been dropped into the <code class="language-plaintext highlighter-rouge">test_env</code> virtual environment. To exit from it use the <code class="language-plaintext highlighter-rouge">deactivate</code> command, again you
can check which version of <code class="language-plaintext highlighter-rouge">python</code> is found on your <code class="language-plaintext highlighter-rouge">$PATH</code> using <code class="language-plaintext highlighter-rouge">which</code>.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="o">(</span>test_env<span class="o">)</span> ❱ deactivate
<span class="o">(</span>test_env<span class="o">)</span> ❱ which python
/usr/bin/python
</code></pre></div></div>

<p>You won’t always create a virtual environment when you want to use it though, that would be a waste of time and
bandwidth downloading and installing packages (although these are cached and used if no new updates are available). To
activate an existing virtual environment you use the <code class="language-plaintext highlighter-rouge">workon</code> command.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code> ❱ workon test_env
<span class="o">(</span>test_env<span class="o">)</span> ❱
</code></pre></div></div>

<h2 id="project-directories">Project Directories</h2>

<p>Typically code for a project resides in its own directory and this can be automatically bound to the virtual environment
using the <code class="language-plaintext highlighter-rouge">mkproject</code> command instead of <code class="language-plaintext highlighter-rouge">mkvirtualenv</code>. The project directory is stored in the <code class="language-plaintext highlighter-rouge">$PROJECT_HOME</code> path
you will have configured during <a href="installation">installation</a>. You can then create a project <em>and</em>  a virtual environment
with…</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>❱ mkproject new_project
<span class="o">(</span>new_project<span class="o">)</span> ❱
</code></pre></div></div>

<p>One advantage this confers is that when you activate the project, e.g. with <code class="language-plaintext highlighter-rouge">workon new_project</code> your working directory
will automatically change to that of the project, i.e. <code class="language-plaintext highlighter-rouge">$PROJECT_HOME/new_project</code>, meaning you don’t have to use <code class="language-plaintext highlighter-rouge">cd</code>
to change directory to that location.</p>

<h3 id="manually-setting-project-directories">Manually setting Project Directories</h3>

<p>If you don’t use <code class="language-plaintext highlighter-rouge">mkproject</code> to create a project you can set it manually after activating a virtual environment using
<code class="language-plaintext highlighter-rouge">setvirtualenvproject</code> in the desired directory. This adds an entry to the <code class="language-plaintext highlighter-rouge">~/.virtualenv/&lt;env_name&gt;/.project</code> file
that reflects the directory associated with the environment.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>❱ mkvirtualenv new_project
<span class="o">(</span>new_project<span class="o">)</span> ❱ <span class="nb">cd</span> ~/work/some/other/path/for/new_project
<span class="o">(</span>new_project<span class="o">)</span> ❱ setvirtualenvproject
</code></pre></div></div>

<h3 id="disabling-switching-to-project-directories">Disabling Switching to Project Directories</h3>

<p>The environment variable <code class="language-plaintext highlighter-rouge">VIRTUALENVWRAPPER_WORKON_CD</code> “<em>controls whether the working directory is changed during the
post activate phase. The default is <code class="language-plaintext highlighter-rouge">1</code>, to enable changing directories. Set the value to <code class="language-plaintext highlighter-rouge">0</code> to disable this behaviour
for all invocations of <code class="language-plaintext highlighter-rouge">workon</code></em>”. If this is something you <em>don’t</em> want to happen you should set this in your
<code class="language-plaintext highlighter-rouge">~/.bashrc</code> or <code class="language-plaintext highlighter-rouge">./zshrc</code>, otherwise the default can be left alone.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="nb">export </span><span class="nv">VIRTUALENVWRAPPER_WORKON_CD</span><span class="o">=</span>0
</code></pre></div></div>

<h2 id="removing-virtual-environments">Removing Virtual Environments</h2>

<p>You can remove a virtual environment with <code class="language-plaintext highlighter-rouge">rmvirtualenv &lt;env_name&gt;</code>.</p>

<p>One neat option if you want to keep a virtual environment but install all packages anew is the ability to remove all
third-party packages in the current virtual environment using <code class="language-plaintext highlighter-rouge">wipeenv</code>. You can then use <code class="language-plaintext highlighter-rouge">pip</code> to reinstall a package’s
dependencies or a set of packages from a <code class="language-plaintext highlighter-rouge">requirements.txt</code> file.</p>

<h2 id="temporary-virtual-environments">Temporary Virtual Environments</h2>

<p>Sometimes you just want to try something out quickly in a clean virtual environment, if for example you are reviewing a
Pull Request and want to check installation and tests pass. <code class="language-plaintext highlighter-rouge">virtualenvwrapper</code> can help here as it has the
<code class="language-plaintext highlighter-rouge">mktmpenv</code>. There are two options here <code class="language-plaintext highlighter-rouge">-c|--cd</code> or <code class="language-plaintext highlighter-rouge">-n|--no-cd</code> which changes directory post-activation or <em>doesn’t</em>
respectively. The environment gets a unique name and will be deleted automatically when it is deactivated.</p>

<h2 id="virtualenvwrapper-hooks"><code class="language-plaintext highlighter-rouge">virtualenvwrapper</code> hooks</h2>

<p>Just like the various hooks available in Git, <a href="https://virtualenvwrapper.readthedocs.io/en/latest/"><code class="language-plaintext highlighter-rouge">virtualenvwrapper</code></a>
also supports <a href="https://virtualenvwrapper.readthedocs.io/en/latest/scripts.html#scripts">hooks</a> that allow scripts to be
run in response to various events. These reside under your <code class="language-plaintext highlighter-rouge">$VIRTUALENVWRAPPER_HOOK_DIR</code> which by default is the same as
your <code class="language-plaintext highlighter-rouge">$WORKON_HOME</code> directory and in a typical standard installation will be <code class="language-plaintext highlighter-rouge">~/.virtualenvs</code>.</p>

<p>The available scripts that are recognised are…</p>

<ul>
  <li><code class="language-plaintext highlighter-rouge">get_env_details</code></li>
  <li><code class="language-plaintext highlighter-rouge">initialize</code></li>
  <li><code class="language-plaintext highlighter-rouge">premkvirtualenv</code></li>
  <li><code class="language-plaintext highlighter-rouge">postmkvirtualenv</code></li>
  <li><code class="language-plaintext highlighter-rouge">precpvirtualenv</code></li>
  <li><code class="language-plaintext highlighter-rouge">postcpvirtualenv</code></li>
  <li><code class="language-plaintext highlighter-rouge">preactivate</code></li>
  <li><code class="language-plaintext highlighter-rouge">postactivate</code></li>
</ul>

<p>Each of these is a simple shell script and will start with the scripting language to use e.g. <code class="language-plaintext highlighter-rouge">#!/usr/bin/bash</code> or
<code class="language-plaintext highlighter-rouge">#!/usr/bin/zsh</code> depending on your shell. You can then script the actions you wish to take when the script is executed.</p>

<h3 id="install-minimal-requirements">Install minimal requirements</h3>

<p>I’m a big fan of <a href="https://dotfiles.github.io">dotfiles</a><sup id="fnref:1" role="doc-noteref"><a href="#fn:1" class="footnote" rel="footnote">1</a></sup>, mine are <a href="https://gitlab.com/nshephard/dotfiles/">hosted on
GitLab</a>, it’s a repository of my configuration files and scripts that I use
regularly across multiple computers.  Because I’m lazy I wrote a couple of <code class="language-plaintext highlighter-rouge">requirements.txt</code> files for installing
packages in my virtual environments.</p>

<ul>
  <li><a href="https://gitlab.com/nshephard/dotfiles/-/blob/master/python/requirements.txt"><code class="language-plaintext highlighter-rouge">requirements.txt</code></a> :
holds everything I might ever want to use in Python.</li>
  <li><a href="https://gitlab.com/nshephard/dotfiles/-/blob/master/python/requirements.txt"><code class="language-plaintext highlighter-rouge">python-lsp-requirements.txt</code></a> :
Install packages for setting up a Python Language Server (which I use from Emacs).</li>
  <li>
    <dl>
      <dt><a href="https://gitlab.com/nshephard/dotfiles/-/blob/master/python/venv_minimal_requirements.txt"><code class="language-plaintext highlighter-rouge">venv_minimal_requirements.txt</code></a></dt>
      <dd>a minimal set of the most common Python packages I am likely to want when creating a new virtual environment.</dd>
    </dl>
  </li>
</ul>

<p>Because I have my <code class="language-plaintext highlighter-rouge">dotfiles</code> cloned to the same location on every computer (<code class="language-plaintext highlighter-rouge">~/dotfiles</code>) I added the following to the
<code class="language-plaintext highlighter-rouge">~/.virtualenvs/postmkvirtualenv</code> <sup id="fnref:2" role="doc-noteref"><a href="#fn:2" class="footnote" rel="footnote">2</a></sup> which will install all of the packages listed in
<code class="language-plaintext highlighter-rouge">~/dotfiles/python/venv_minimal_requirements.txt</code> whenever I create a new virtual environment, whether that is with
<code class="language-plaintext highlighter-rouge">mkvirtualenv</code> or <code class="language-plaintext highlighter-rouge">mktmpenv</code>.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code>pip <span class="nb">install</span> <span class="nt">--no-cache-dir</span> <span class="nt">-r</span> ~/dotfiles/python/venv_minimal_requirements.txt
</code></pre></div></div>

<p>This ensures the latest versions of each package listed in <code class="language-plaintext highlighter-rouge">~/dotfiles/python/venv_minimal_requirements.txt</code> were
downloaded and installed as the <code class="language-plaintext highlighter-rouge">--no-cache-dir</code> prevents using cached versions of packages.</p>

<h3 id="a-smarter-script">A smarter script</h3>

<p>This served me well for a time, but occasionally I found I <em>didn’t</em> want to install <em>any</em> packages in a new virtual
environment (most often when testing new branches using <code class="language-plaintext highlighter-rouge">mktmpenv</code>) and I’d have to remember to comment out the line in
the hook file (<code class="language-plaintext highlighter-rouge">~/.virtualenvs/postmkvirtualenv</code>) before creating the environment. Typically though I’d forget to do
this and would have to halt installation of required packages, deactivate the environment, <em>then</em> comment it out and
create a new environment.</p>

<p>This quickly became irksome.</p>

<p>But <code class="language-plaintext highlighter-rouge">~/.virtualenvs/postmkvirtualenv</code> is just a script and so we can use a bit of scripting knowledge to make it
interactive and ask the user if they want to install the packages listed in <code class="language-plaintext highlighter-rouge">venv_minimal_requirements.txt</code>. I found a
really useful answer on StackOverflow in the <a href="https://stackoverflow.com/a/226724/1444043">How do I prompt for yes/no/cancel input in a Linux shell
script</a> that showed several different ways to prompt the user for a response
as to whether they want to do something.</p>

<p>I therefore updated my
<a href="https://gitlab.com/nshephard/dotfiles/-/blob/master/python/postmkvirtualenv?ref_type=heads"><code class="language-plaintext highlighter-rouge">~/.virtualenvs/postmkvirtualenv</code></a>
to the following which prompts for a numeric response, <code class="language-plaintext highlighter-rouge">1</code> for <code class="language-plaintext highlighter-rouge">Yes</code> and <code class="language-plaintext highlighter-rouge">2</code> for <code class="language-plaintext highlighter-rouge">No</code> and takes the appropriate action,
installing using my original invocation of <code class="language-plaintext highlighter-rouge">pip</code> if I want to install packages and enter <code class="language-plaintext highlighter-rouge">1</code> or installing nothing if I
enter <code class="language-plaintext highlighter-rouge">2</code>.</p>

<div class="language-bash highlighter-rouge"><div class="highlight"><pre class="highlight"><code><span class="c">#!/usr/bin/zsh</span>
<span class="c"># This hook is sourced after a new virtualenv is activated.</span>


<span class="nb">echo</span> <span class="s2">"Do you wish to install minimal requirements (from venv_minimal_requirements.txt)? "</span>
<span class="k">select </span>yn <span class="k">in</span> <span class="s2">"Yes"</span> <span class="s2">"No"</span><span class="p">;</span> <span class="k">do
  case</span> <span class="nv">$yn</span> <span class="k">in
    </span>Yes <span class="p">)</span> pip <span class="nb">install</span> <span class="nt">--no-cache-dir</span> <span class="nt">-r</span> ~/dotfiles/python/venv_minimal_requirements.txt<span class="p">;</span> <span class="nb">break</span><span class="p">;;</span>
    No <span class="p">)</span> <span class="nb">echo</span> <span class="s2">"No packages installed. install packages with 'pip'.</span><span class="se">\n</span><span class="s2">"</span><span class="p">;</span> <span class="nb">break</span><span class="p">;;</span>
  <span class="k">esac</span>
<span class="k">done</span>
</code></pre></div></div>

<p><strong>NB</strong> You may want to tweak the opening shebang if you use the Bash shell.</p>

<h2 id="drawbacks">Drawbacks</h2>

<p>There are a couple of drawbacks I’ve found to using using <code class="language-plaintext highlighter-rouge">virtualenvwrapper</code>.</p>

<p>The first is that <code class="language-plaintext highlighter-rouge">mkproject</code> doesn’t allow nesting of project directories, you have to specify a single directory and
it will be created under the <code class="language-plaintext highlighter-rouge">$PROJECT_HOME</code> directory with the associated environment name. This doesn’t work for me as
I use the structure <code class="language-plaintext highlighter-rouge">~/work/git</code> as the base but then have sub-directories based on the Git Forge
(<a href="https://github.com">GitHub</a>/<a href="https://gitlab.com">GitLab</a>/<a href="https://codeberg.org/">Codeberg</a>) the repository is
associated with and further nesting to reflect the user/organisation within as I have both a personal and work
accounts. E.g. <code class="language-plaintext highlighter-rouge">~/work/git/hub/ns-rse/ns-rse.github.io</code> which is the source
(<a href="https://github.com/ns-rse/ns-rse.github.io">github.com/ns-rse/ns-rse.github.io</a>) for my
<a href="https://blog.nshephard.dev">blog</a> hosted in GitHub under my work account (<code class="language-plaintext highlighter-rouge">ns-rse</code>) or
<code class="language-plaintext highlighter-rouge">~/work/git/lab/nshephard/tcx2gpx</code> which is a project of mine (<a href="https://pypi.org/project/tcx2gpx">tcx2gpx</a>) which is
<a href="https://gitlab.com/nshephard/tcx2gpx">hosted on GitLab</a>.</p>

<p>This means that if I wanted to create a project with <code class="language-plaintext highlighter-rouge">mkproject</code> based on <code class="language-plaintext highlighter-rouge">$PROJECT_HOME</code> being <code class="language-plaintext highlighter-rouge">/work/git</code> following
this structure I would specify <code class="language-plaintext highlighter-rouge">mkproject  git/lab/new_project</code> and whilst the directory is created, the virtual
environment is created as <code class="language-plaintext highlighter-rouge">git/lab/new_project</code> which is truncated to <code class="language-plaintext highlighter-rouge">git</code> and you can’t <code class="language-plaintext highlighter-rouge">workon git</code> because the
activation scripts are nested deeper under <code class="language-plaintext highlighter-rouge">git/lab/new_project</code>. Further each environment I created would then
conflict. I could probably work around this by creating symbolic links but in practice I just use <code class="language-plaintext highlighter-rouge">mkvirtualenv</code> and
<code class="language-plaintext highlighter-rouge">setvirtualenvproject</code> after I <code class="language-plaintext highlighter-rouge">git clone</code> work.</p>

<p>This is a problem specifically of my own creation though and I can live with it/work around it.</p>

<p>Something other users might find causes greater friction is that <code class="language-plaintext highlighter-rouge">virtualenvwrapper</code> doesn’t support creating and
keeping the virtual environments within the project directory itself. This is never something that I’ve wanted to do
myself though as I find it tidier to keep them all in one place and easier to find and remove obsolete environments.</p>

<h2 id="conclusion">Conclusion</h2>

<p>There are many options for installing and managing Python Virtual Environments including those provided by package
development frameworks such as <a href="https://hatch.pypa.io/latest/">Hatch</a>, <a href="https://pdm-project.org/latest/">PDM</a> and
<a href="https://python-poetry.org/">Poetry</a> but <a href="https://virtualenvwrapper.readthedocs.io/en/latest/"><code class="language-plaintext highlighter-rouge">virtualenvwrapper</code></a> is a
viable option that has many neat features, more than covered here, that make working with virtual environments
straight-forward. The <a href="https://virtualenvwrapper.readthedocs.io/en/latest/">documentation</a> is excellent and worth
reading in detail if this introductory article has sparked your interest as there are more than options than those
covered here.</p>

<p><strong>NB</strong> This post is based on (and hopefully improves on) two earlier blogs made by the author. Most of the improvements
are Thanks to my colleagues <em>Tamora James</em> and <em>Pete Heywood</em> who reviewed a draft and provided feedback.</p>

<ul>
  <li><a href="https://blog.nshephard.dev/posts/virtualenvwrapper/">virtualenvwrapper</a></li>
  <li><a href="https://blog.nshephard.dev/posts/virtualenv-hooks/">virtualenvwrapper hooks</a></li>
</ul>

<h2 id="links">Links</h2>

<ul>
  <li><a href="https://www.anaconda.com/">Anaconda</a></li>
  <li><a href="https://hatch.pypa.io/latest/">Hatch</a></li>
  <li><a href="https://pdm-project.org/latest/">PDM</a></li>
  <li><a href="https://github.com/pypa/pipx">pipx</a></li>
  <li><a href="https://python-poetry.org/">Poetry</a></li>
  <li><a href="https://docs.python.org/3/library/venv.html">venv</a></li>
  <li><a href="https://virtualenv.pypa.io/en/latest/">virtualenv</a></li>
  <li><a href="https://virtualenvwrapper.readthedocs.io/en/latest/">virtualenvwrapper</a></li>
</ul>

<div class="footnotes" role="doc-endnotes">
  <ol>
    <li id="fn:1" role="doc-endnote">
      <p>There is a wealth of information on what you can do with your <code class="language-plaintext highlighter-rouge">dotfiles</code> but that is an article in itself and I’m
yet to write it. A useful set of different aliases you could use can be found
<a href="https://dotfiles.io/about/#introduction">here</a>. <a href="#fnref:1" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
    <li id="fn:2" role="doc-endnote">
      <p>Actually I create the script in
<a href="https://gitlab.com/nshephard/dotfiles/-/blob/master/python/postmkvirtualenv?ref_type=heads"><code class="language-plaintext highlighter-rouge">~/dotfiles/python/postmkvirtualenv</code></a>
and made a symbolic link at <code class="language-plaintext highlighter-rouge">~/.virtualenv/postmkvirtualenv</code> that points to it so that whenever I update or improve
this script it is updated across my computers. <a href="#fnref:2" class="reversefootnote" role="doc-backlink">&#8617;</a></p>
    </li>
  </ol>
</div>]]></content><author><name>Neil Shephard</name></author><category term="python" /><category term="&quot;virtual" /><category term="environment&quot;" /><category term="anaconda" /><category term="virtualenvwrapper" /><category term="pip" /><summary type="html"><![CDATA[This article introduces virtualenvwrapper for creating and working with Python Virtual Environments showing how to install and use it and highlighting some useful features.]]></summary></entry><entry><title type="html">Best Practices in AI Afternoon Event Summary</title><link href="https://rse.shef.ac.uk/blog/2024-07-31-best-practices-in-ai-afternoon-event-summary/" rel="alternate" type="text/html" title="Best Practices in AI Afternoon Event Summary" /><published>2024-07-31T10:00:00+01:00</published><updated>2024-07-31T10:00:00+01:00</updated><id>https://rse.shef.ac.uk/blog/2024-07-31-best-practices-in-ai-afternoon-event-summary</id><content type="html" xml:base="https://rse.shef.ac.uk/blog/2024-07-31-best-practices-in-ai-afternoon-event-summary/"><![CDATA[<div style="margin-top: 1em; margin-bottom: 1em;">
<img src="/assets/images/2024-07-05-best-practices-in-ai/banner-gforms.svg" alt="Best Practices in AI Afternoon Banner" />
</div>

<p>We’ve finally put all the videos, slides and other resources together from the <a href="/events/seminar-2024-07-05-best-practices-in-ai-afternoon">Best Practices in AI Afternoon</a>
event that happened on the 5th of July 2024. You can find them listed below.</p>

<!--more-->

<h3 id="maximizing-efficiency-in-large-language-models-compute-memory-and-fine-tuning">Maximizing Efficiency in Large Language Models: Compute, Memory, and Fine-Tuning</h3>
<p><strong><img class="align-self-center mr-2" src="/assets/images/icons/icons8-communication-skill-50.png" width="20" alt="Speaker" /> Karin Sevegnani, Senior Solutions Architect, Nvidia</strong></p>

<p>In this talk, we will explore the intricate balance between computational resources, memory limitations, and parameter-efficient fine-tuning techniques in large language models (LLMs). We will analyse strategies to optimize the performance of LLMs while managing these constraints effectively. From efficient memory utilization to streamlined parameter fine-tuning methods, we will discuss practical approaches to maximize the efficiency of LLMs without sacrificing performance.</p>

<iframe id="kaltura_player" type="text/javascript" src="https://cdnapisec.kaltura.com/p/2103181/embedPlaykitJs/uiconf_id/53345422?iframeembed=true&amp;entry_id=1_3uimk13k&amp;config[provider]={&quot;widgetId&quot;:&quot;1_08d7ws2x&quot;}&amp;config[playback]={&quot;startTime&quot;:0}" style="width: 400px;height: 285px;border: 0;" allowfullscreen="" webkitallowfullscreen="" mozallowfullscreen="" allow="autoplay *; fullscreen *; encrypted-media *" sandbox="allow-downloads allow-forms allow-same-origin allow-scripts allow-top-navigation allow-pointer-lock allow-popups allow-modals allow-orientation-lock allow-popups-to-escape-sandbox allow-presentation allow-top-navigation-by-user-activation" title="Maximizing Efficiency in Large Language Models: Compute, Memory, and Fine-Tuning"></iframe>

<ul>
  <li><a href="https://nvidia-gpugenius.highspot.com/viewer/668bacf0b742e161aab7e95c?iid=6688069f3f35f83f5dd60161">Presentation slides</a></li>
</ul>

<h3 id="docker-for-machine-learning">Docker for Machine Learning</h3>
<p><strong><img class="align-self-center mr-2" src="/assets/images/icons/icons8-communication-skill-50.png" width="20" alt="Speaker" /> Ryan Daniels, University of Cambridge</strong></p>

<p>Writing research software in Python presents numerous challenges to reproducibility - what version of Python is being used? What about the versions of PyTorch, Scikit Learn or Numpy? Should we use Conda, or venv, or Poetry to manage dependencies and environments? How can we control randomness? Do I have the right version of Cuda Toolkit? In principle, given the same data, and same algorithms and methodology, we should be able to reproduce the results of any given experiment to within an acceptable degree of error. Dealing with the above questions introduces significant problems to reproducing experiments in machine learning. In this talk, I would like to convince you that Docker can help alleviate almost all of these questions. Furthermore, combining Docker, git and GitHub can be a powerful workflow, helping to minimise your tech stack, and declutter your python development experience.</p>

<iframe id="kaltura_player" type="text/javascript" src="https://cdnapisec.kaltura.com/p/2103181/embedPlaykitJs/uiconf_id/53345422?iframeembed=true&amp;entry_id=1_ea910iqv&amp;config[provider]={&quot;widgetId&quot;:&quot;1_foxtxokg&quot;}&amp;config[playback]={&quot;startTime&quot;:0}" style="width: 400px;height: 285px;border: 0;" allowfullscreen="" webkitallowfullscreen="" mozallowfullscreen="" allow="autoplay *; fullscreen *; encrypted-media *" sandbox="allow-downloads allow-forms allow-same-origin allow-scripts allow-top-navigation allow-pointer-lock allow-popups allow-modals allow-orientation-lock allow-popups-to-escape-sandbox allow-presentation allow-top-navigation-by-user-activation" title="Docker for Research Software"></iframe>

<ul>
  <li><a href="/assets/slides/2024-07-05-best-practices-ai/docker_for_rse.pdf">Presentation slides</a></li>
</ul>

<h3 id="how-do-you-unit-test-an-ml-model">How do you unit test an ML model?</h3>
<p><strong><img class="align-self-center mr-2" src="/assets/images/icons/icons8-communication-skill-50.png" width="20" alt="Speaker" /> Wahab Kawafi, University of Bristol</strong></p>

<p>Covering methods such as mock testing, simulation, experiment tracking, and dataset curation. With examples in medicine, chemistry, aerospace engineering, and LLMs.</p>

<iframe id="kaltura_player" type="text/javascript" src="https://cdnapisec.kaltura.com/p/2103181/embedPlaykitJs/uiconf_id/53345422?iframeembed=true&amp;entry_id=1_2yuxckko&amp;config[provider]={&quot;widgetId&quot;:&quot;1_b9fcv3r6&quot;}&amp;config[playback]={&quot;startTime&quot;:0}" style="width: 400px;height: 285px;border: 0;" allowfullscreen="" webkitallowfullscreen="" mozallowfullscreen="" allow="autoplay *; fullscreen *; encrypted-media *" sandbox="allow-downloads allow-forms allow-same-origin allow-scripts allow-top-navigation allow-pointer-lock allow-popups allow-modals allow-orientation-lock allow-popups-to-escape-sandbox allow-presentation allow-top-navigation-by-user-activation" title="How do you unit test an ML model?"></iframe>

<ul>
  <li><a href="/assets/slides/2024-07-05-best-practices-ai/unit_test_ml_model.pdf">Presentation slides</a></li>
</ul>

<h3 id="how-to-make-your-machine-learning-code-faster">How to make your machine learning code faster</h3>
<p><strong><img class="align-self-center mr-2" src="/assets/images/icons/icons8-communication-skill-50.png" width="20" alt="Speaker" /> Edwin Brown, Research Software Engineering, University of Sheffield</strong></p>

<p>Practical guide to profile machine learning code to find bottlenecks and to remove these bottlenecks.</p>

<iframe id="kaltura_player" type="text/javascript" src="https://cdnapisec.kaltura.com/p/2103181/embedPlaykitJs/uiconf_id/53345422?iframeembed=true&amp;entry_id=1_zy2js5xq&amp;config[provider]={&quot;widgetId&quot;:&quot;1_2ewj75mj&quot;}&amp;config[playback]={&quot;startTime&quot;:0}" style="width: 400px;height: 285px;border: 0;" allowfullscreen="" webkitallowfullscreen="" mozallowfullscreen="" allow="autoplay *; fullscreen *; encrypted-media *" sandbox="allow-downloads allow-forms allow-same-origin allow-scripts allow-top-navigation allow-pointer-lock allow-popups allow-modals allow-orientation-lock allow-popups-to-escape-sandbox allow-presentation allow-top-navigation-by-user-activation" title="How to make your machine learning code faster"></iframe>

<ul>
  <li><a href="/assets/slides/2024-07-05-best-practices-ai/Profiling-ML-Code-with-Pytorch.pdf">Presentation slides</a></li>
  <li><a href="https://github.com/EdwinB12/ProfileML">Code repository</a></li>
</ul>

<h3 id="nvidia-self-paced-training-courses-and-other-ml-resources">Nvidia Self-paced training courses and other ML resources</h3>
<p><strong><img class="align-self-center mr-2" src="/assets/images/icons/icons8-communication-skill-50.png" width="20" alt="Speaker" /> Denis Battistella, Higher Education and Research, Nvidia</strong></p>

<iframe id="kaltura_player" type="text/javascript" src="https://cdnapisec.kaltura.com/p/2103181/embedPlaykitJs/uiconf_id/53345422?iframeembed=true&amp;entry_id=1_e5azrc8x&amp;config[provider]={&quot;widgetId&quot;:&quot;1_1lxy6j2c&quot;}&amp;config[playback]={&quot;startTime&quot;:0}" style="width: 400px;height: 285px;border: 0;" allowfullscreen="" webkitallowfullscreen="" mozallowfullscreen="" allow="autoplay *; fullscreen *; encrypted-media *" sandbox="allow-downloads allow-forms allow-same-origin allow-scripts allow-top-navigation allow-pointer-lock allow-popups allow-modals allow-orientation-lock allow-popups-to-escape-sandbox allow-presentation allow-top-navigation-by-user-activation" title="Nvidia Self-paced Training Courses"></iframe>

<p>Links to the resources discussed in the presentation:</p>

<ul>
  <li>Training from Nvidia:
    <ul>
      <li><a href="https://www.nvidia.com/en-gb/training/">Deep Learning Institute and Training Solutions</a></li>
      <li><a href="https://www.nvidia.com/en-gb/training/online/">Self-paced training courses</a></li>
      <li><a href="https://learn.nvidia.com/en-us/training/instructor-led-workshops">Instructor-led workshops</a></li>
      <li><a href="https://www.nvidia.com/en-gb/training/educator-programs/university-ambassador-program/">DLI University Ambassador Program</a></li>
      <li><a href="https://www.nvidia.com/en-gb/training/educator-programs/">Deep Learning Programs for Educators</a></li>
      <li>Twin Karmakharm (<a href="t.karmakharm@sheffield.ac.uk">t.karmakharm@sheffield.ac.uk</a>) of the RSE group is the University of Sheffield’s local DLI ambassador and can help with access to the above training resources.</li>
    </ul>
  </li>
  <li>PhD fellowships: <a href="https://research.nvidia.com/graduate-fellowships#gf-section-graduate-fellows-">https://research.nvidia.com/graduate-fellowships#gf-section-graduate-fellows-</a></li>
  <li>Accelerated software:
    <ul>
      <li>Denis touched upon <a href="https://www.nvidia.com/en-us/gpu-cloud/">NGC</a>: software repository for accelerated software, including SDKs, frameworks, containers – which you can download and deploy for free. Regularly updated.</li>
      <li>New released <a href="https://www.nvidia.com/en-gb/ai/">NIM</a> accelerated inference microservices to accelerate the deployment of Gen AI models.</li>
    </ul>
  </li>
</ul>

<h3 id="acknowledgements">Acknowledgements</h3>

<p>We’d like to say thank you to all the speakers and attendees for making <a href="/events/seminar-2024-07-05-best-practices-in-ai-afternoon">Best Practices in AI Afternoon</a>
a great success!</p>

<p>Thank you to Emma and Kate from the <a href="https://www.sheffield.ac.uk/machine-intelligence">Centre for Machine Intelligence (CMI)</a> for all the help with
organising the event and the <a href="https://www.sheffield.ac.uk/machine-intelligence">CMI</a> and Nvidia for sponsoring the event.</p>

<h3 id="photos-from-the-day">Photos from the day</h3>

<p><img src="/assets/slides/2024-07-05-best-practices-ai/P1022846.jpg" alt="Karin Sevegnani presenting" />
<em>Karin Sevegnani presenting “Maximizing Efficiency in Large Language Models: Compute, Memory, and Fine-Tuning”</em></p>

<p><img src="/assets/slides/2024-07-05-best-practices-ai/P1022853.jpg" alt="Ryan Daniels presenting" />
<em>Ryan Daniels presenting “Docker for Machine Learning”</em></p>

<p><img src="/assets/slides/2024-07-05-best-practices-ai/P1022858.jpg" alt="Edwin Brown presenting" />
<em>Edwin Brown presenting “How to make your machine learning code faster”</em></p>

<p><img src="/assets/slides/2024-07-05-best-practices-ai/P1022860.jpg" alt="Bob Turner presenting" />
<em>Bob Turner presenting “From Research Software to Software as a Service”</em></p>

<p><img src="/assets/slides/2024-07-05-best-practices-ai/P1022862.jpg" alt="Denis Battistella presenting" />
<em>Denis Battistella presenting “Nvidia Self-paced Training Courses”</em></p>

<p><img src="/assets/slides/2024-07-05-best-practices-ai/P1022863.jpg" alt="Q &amp; A Panel" />
<em>Q &amp; A Panel with Andy Grant, Edwin Brown, Ryan Daniels, and Christopher Wild</em></p>]]></content><author><name>Twin Karmakharm and Christopher Wild</name></author><category term="AI" /><category term="LLM" /><category term="Docker" /><category term="Testing" /><summary type="html"><![CDATA[We’ve finally put all the videos, slides and other resources together from the Best Practices in AI Afternoon event that happened on the 5th of July 2024. You can find them listed below.]]></summary></entry><entry><title type="html">Upgrading R to at least version 4.4.0</title><link href="https://rse.shef.ac.uk/blog/2024-07-19-faqs-for-upgrading-r/" rel="alternate" type="text/html" title="Upgrading R to at least version 4.4.0" /><published>2024-07-19T10:00:00+01:00</published><updated>2024-07-19T10:00:00+01:00</updated><id>https://rse.shef.ac.uk/blog/2024-07-19-faqs-for-upgrading-r</id><content type="html" xml:base="https://rse.shef.ac.uk/blog/2024-07-19-faqs-for-upgrading-r/"><![CDATA[<h1 id="upgrading-r-to-at-least-version-440">Upgrading R to at least version 4.4.0</h1>

<p>Due to a security vulnerability, all users are advised to update their installation of R to version 4.4.0 or newer as soon as possible (ideally within the next month).
<!--more--></p>

<ul>
  <li><a href="#yoyo-and-managed-desktop-users">YoYo and Managed Desktop users</a></li>
  <li><a href="#unmanaged-or-ronin-users">Unmanaged or Ronin users</a></li>
  <li><a href="#university-of-sheffield-hpc-users">University of Sheffield HPC users</a></li>
  <li><a href="#faqs">FAQs</a></li>
  <li><a href="#general-advice">General advice</a></li>
</ul>

<h2 id="background">Background</h2>

<p>We want to bring to your attention the security risks associated with handling R data files (with the file extension .rds and .rdx).  While the University has not experienced any cyber security incidents as a result of this vulnerability, it is imperative to remain vigilant and informed about potential threats and act accordingly.</p>

<p>A vulnerability (<a href="https://hiddenlayer.com/research/r-bitrary-code-execution/">CVE-2024-27322</a>) has been identified in the R language that allows attackers to run any code they want without your permission when certain types of (maliciously-crafted) data files are loaded, which could potentially lead to unauthorised access, manipulation of systems or unauthorised exporting of data. This vulnerability affects RDS (R Data Serialization) format files and RDX (R database index) files. Attackers can exploit this by crafting malicious RDS or RDX files to execute arbitrary commands on the target device. The vulnerability arises from how R implements data loading, particularly through the readRDS function, used to load RDS and RDX files. Despite expectations that loaded files don’t run code, this vulnerability allows for unauthorised code execution.</p>

<p>The most concerning aspects of this exploit have been fixed in R 4.4.0 (with 4.4.1 being the newest version at the time of writing) and we strongly recommend that all R users at the University of Sheffield upgrade their R version immediately. However, it is important to note that there will continue to be a risk when using RDS or RDX files from untrusted sources, regardless of whether you are using R &gt;= 4.4.0. As always, members of the University of Sheffield should use their best judgement when running code from sources outside of the University.</p>

<h2 id="yoyo-and-managed-desktop-users">YoYo and Managed Desktop users</h2>

<p>The upgrade to R &gt;= 4.4.0 will happen automatically in late July and you will not need to take any further action to update R itself. You will need to recreate your R package library for R &gt;= 4.4.0 - reinstalling any R packages that you currently need/use (using e.g. <code class="language-plaintext highlighter-rouge">update.packages()</code>).</p>

<h2 id="unmanaged-machine-or-ronin-users">Unmanaged machine or Ronin users</h2>

<p>We recommend that you have a recent <em>backup</em> of your files before beginning the update.</p>

<ol>
  <li>Go to the <a href="https://cran.r-project.org/">R project’s website</a>
    <ul>
      <li>Choose the appropriate installer option from the list based on your machine.  <img src="/assets/images/2024-06-05-faqs-for-upgrading-r/upgrading-r-rstudio-r-website-downloads.png" alt="Downloads on the R website" /></li>
    </ul>
  </li>
  <li>Navigate to the precompiled package:
    <ul>
      <li>For <em>Windows</em> machines:
        <ul>
          <li>Choose <em>base</em></li>
          <li>Click <em>Download R 4.4.1 for Windows</em>.</li>
          <li>Open the downloaded file and follow the installation instructions.</li>
        </ul>
      </li>
      <li>For <em>Mac</em> machines:
        <ul>
          <li>Choose the .pkg file that is appropriate for your macOS version and architecture.</li>
          <li>Open the downloaded file and follow the installation instructions.</li>
        </ul>
      </li>
    </ul>
  </li>
  <li>When the installer has completed, open R Studio. In the <em>Tools</em> menu, select <em>Global Options…</em>   <img src="/assets/images/2024-06-05-faqs-for-upgrading-r/upgrading-r-rstudio-tools-menu.png" alt="Tools menu in RStudio" /></li>
  <li>On the <em>General</em> settings page, in the <em>R Sessions</em> section,  view the file path under <em>R Version</em> and click <em>Change…</em></li>
  <li>Choose R version 4.4.1 from the pop up file explorer. Click OK.   <img src="/assets/images/2024-06-05-faqs-for-upgrading-r/upgrading-r-rstudio-version-selection.png" alt="R version selection in RStudio" /></li>
  <li>Restart RStudio when prompted.</li>
  <li>(Re)install the R packages you use in your work (your R package library is specific to the version of R you’re using) .</li>
  <li>Test your workflows with R 4.4.1</li>
  <li>Delete your older version(s) of R.
    <ol>
      <li>To do this, open your file explorer and navigate to where your base R files are located. Use the file path from step 4 to guide you to the files if they are not obvious.  <img src="/assets/images/2024-06-05-faqs-for-upgrading-r/upgrading-r-rstudio-r-folder-deletion.png" alt="Picking old versions to delete" /></li>
      <li>Right click on the older version(s) and select <em>Delete</em>.</li>
    </ol>
  </li>
  <li>When all the old versions have been deleted, the upgrade task is complete.</li>
</ol>

<h2 id="university-of-sheffield-hpc-users">University of Sheffield HPC users</h2>

<p>The versions of R centrally installed on Stanage and Bessemer may be older than 4.4.0. Those installations have recently been updated to include a fix for the vulnerability.</p>

<p>If you’re using R via Conda on Bessemer or Stanage, see the <em>guidance for Conda</em> below.</p>

<h2 id="faqs">FAQs</h2>

<h3 id="what-are-rds-and-rdx-data-files-for-r-rds-rdx-and-why-are-they-used">What are RDS and RDX data files for R (.rds, .rdx), and why are they used?</h3>

<p>These are binary files used to store R objects such as data frames, lists, functions, and other R data structures. They are commonly used for saving and loading data within the R programming environment.</p>

<h3 id="do-i-have-to-upgrade-to-r-440-or-newer">Do I have to upgrade to R 4.4.0 or newer?</h3>

<p>Upgrading to R &gt;= 4.4.0 is mandatory as it addresses recent security vulnerabilities. It’s important to remember that even with the latest version there is still a risk with untrusted RDS files.</p>

<h3 id="how-long-will-it-take-to-upgrade">How long will it take to upgrade?</h3>

<p>The time to upgrade to &gt;= 4.4.0 can range from 2 minutes to 30 mins depending on the internet speed and other factors.</p>

<h3 id="how-do-i-upgrade-r-versions-when-using-conda-or-docker-containers">How do I upgrade R versions when using Conda or Docker containers?</h3>

<p>Upgrading R versions within Conda or Docker containers is typically straightforward due to their support for a drop-in replacement approach. However, certain considerations and best practices can streamline the process and mitigate potential complexities.</p>

<h3 id="upgrading-r-in-conda-environments">Upgrading R in Conda environments</h3>

<p>To upgrade R in your Conda environment, you can use the following command:</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>conda <span class="nb">install</span> <span class="nt">-c</span> conda-forge r-base&gt;<span class="o">=</span>4.4
</code></pre></div></div>

<p>Significant changes, such as a compiler or low-level library update, may necessitate updates to every package in the environment. In such cases, creating a new environment based on the same specifications might offer a simpler solution.</p>

<h3 id="upgrading-r-in-docker-containers">Upgrading R in Docker containers</h3>

<p>To upgrade R in a Docker container, ensure that the Docker image’s R version meets your requirements. Typically, you specify the desired R version in the Dockerfile, ensuring compatibility with your application’s dependencies.</p>

<div class="language-sh highlighter-rouge"><div class="highlight"><pre class="highlight"><code>Docker image r-base version <span class="o">&gt;=</span> 4.4
</code></pre></div></div>

<p>One potential issue arises if the older Conda environments rely on different compiler or library versions that are incompatible with the new R version or other dependencies within the environment. In such cases, addressing compatibility issues may require a solve-by-issue approach, where each problem is tackled individually. This could involve updating dependencies, modifying the environment configuration, or seeking alternative solutions depending on the specific challenges encountered.</p>

<h3 id="what-if-my-workflow-is-dependent-on-an-older-version-of-r">What if my workflow is dependent on an older version of R?</h3>

<p>We advise you to start testing your workflow on the new version, documenting any warnings or errors that might arise. You can book a <a href="https://rse.shef.ac.uk/support/code-clinic/">Code Clinic</a> with the Research Software Engineering (RSE) team, to discuss your specific workflow and concerns in detail and get hands-on assistance with debugging any errors or adapting your code to the new version.</p>

<h3 id="can-we-always-trust-packages-downloaded-from-cran">Can we always trust packages downloaded from CRAN?</h3>

<p>While CRAN offers some security measures, using a package from CRAN isn’t guaranteed to be entirely-risk free. Always use your best judgement.</p>

<h3 id="whats-new-in-r-440">What’s new in R 4.4.0?</h3>

<p>Changes in R version 4.4.0 can be found in <a href="https://cran.r-project.org/bin/windows/base/NEWS.R-4.4.0.html">R News Documentation</a>.</p>

<h3 id="what-if-i-dont-use-r-studio-as-my-default-environment-for-r">What if I don’t use R Studio as my default environment for R?</h3>

<p>We recommend that you read the documentation for your operating system / chosen operating system package manager (if applicable). If you cannot find an appropriate method, then we recommend starting the update process by either uninstalling the older version of base R or (less preferable) manually deleting the base R files before downloading and installing version &gt;= 4.4.0.  The FAQs linked to from <a href="https://cloud.r-project.org/">https://cloud.r-project.org/</a> may also be useful.</p>

<h2 id="general-advice">General advice</h2>

<ol>
  <li>Use trusted sources
    <ul>
      <li>Use packages from a reputable source with a history of well-maintained packages.</li>
      <li>Use only serialised (<code class="language-plaintext highlighter-rouge">.Rds</code> / <code class="language-plaintext highlighter-rouge">.Rdx</code>) objects from trusted sources; be very wary of such files shared openly on the internet.</li>
    </ul>
  </li>
  <li>Regular updates
    <ul>
      <li>Keep your R environment and packages up-to-date with the latest security patches.</li>
    </ul>
  </li>
  <li>Data minimisation
    <ul>
      <li>Store only the data essential for your analysis to reduce the risk of a data breach. If you have sensitive data, consider storing it separately in a secure location to minimise the data at risk.</li>
    </ul>
  </li>
  <li>Version control
    <ul>
      <li>Implement version control strategies to track changes and manage your codebase effectively.</li>
    </ul>
  </li>
  <li>Maintain test cases
    <ul>
      <li>Develop simple test cases that can be used to validate your code’s results to make it easier and more reliable to upgrade between versions of R and other packages.</li>
    </ul>
  </li>
</ol>]]></content><author><name>Grace Accad, Gemma Ives, Will Furnass</name></author><category term="R" /><category term="rstats" /><category term="security" /><summary type="html"><![CDATA[Upgrading R to at least version 4.4.0 Due to a security vulnerability, all users are advised to update their installation of R to version 4.4.0 or newer as soon as possible (ideally within the next month).]]></summary></entry><entry><title type="html">Bede Tier 2 HPC: Nvidia Grace-Hopper Superchip Pilot</title><link href="https://rse.shef.ac.uk/blog/2024-05-08-bede-tier-2-hpc-nvidia-grace-hopper-superchip/" rel="alternate" type="text/html" title="Bede Tier 2 HPC: Nvidia Grace-Hopper Superchip Pilot" /><published>2024-05-08T15:00:00+01:00</published><updated>2024-05-08T15:00:00+01:00</updated><id>https://rse.shef.ac.uk/blog/2024-05-08-bede-tier-2-hpc-nvidia-grace-hopper-superchip</id><content type="html" xml:base="https://rse.shef.ac.uk/blog/2024-05-08-bede-tier-2-hpc-nvidia-grace-hopper-superchip/"><![CDATA[<h2 id="gh200-gpus-now-available-in-n8-cir-bede">GH200 GPUs now available in N8 CIR Bede</h2>

<p>Members of the University of Sheffield have access to a range of GPU resources for carrying out their research, available in local (Tier 3) and affiliated regional (Tier 2) HPC systems.</p>

<p><strong>As of March 2024, the <a href="https://docs.hpc.shef.ac.uk/en/latest/other-uk-hpc-resources/bede.html">N8 CIR Bede Tier 2 HPC facility</a> now includes an <a href="https://bede-documentation.readthedocs.io/en/latest/usage/index.html#grace-hopper-pilot">Open Pilot of 3 NVIDIA GH200 Nodes</a> which are available to all users</strong>.</p>

<p>Each GH200 node in Bede contains a single <a href="https://www.nvidia.com/en-us/data-center/grace-hopper-superchip/">NVIDIA GH200 Grace Hopper Superchip</a> - a 72 core NVIDIA Grace ARM CPU connected to a single <a href="https://resources.nvidia.com/en-us-tensor-core">NVIDIA Hopper GPU</a> via a 900GB/s <a href="https://www.nvidia.com/en-us/data-center/nvlink-c2c/">NVIDIA NVLink-C2C</a> interconnect.
This new interconnect allows data to be moved between the host and device with a much higher bandwidth than in traditional PCI-e based systems, reducing the time spent transferring data.</p>

<!--more-->

<p>The following figure shows the theoretical peak bandwidth for the range of GPU interconnect technologies used in a range of GPUs.</p>

<p><img src="/assets/images/2024-05-08-bede-tier-2-hpc-nvidia-grace-hopper-superchip/gpu-interconnects-tuos.png" alt="Figure 1: GPU host-device interconnect theoretical peak bandwidth" />
Source: <a href="https://github.com/ptheywood/gpu-interconnect-plots">github.com/ptheywood/gpu-interconnect-plots</a></p>

<h3 id="pytorch-llm-fine-tuning-benchmark">PyTorch LLM Fine-tuning Benchmark</h3>

<p>To illustrate the performance of the GH200 GPUs for machine learning workloads, a benchmark of LLM fine-tuning previously used by <a href="https://www.farhadallian.co.uk/">Farhad Allian</a> (a Research Data Engineer in <a href="https://www.sheffield.ac.uk/it-services/about">Research &amp; Innovation IT</a>)  to <a href="https://notesrcg.blogspot.com/2023/12/blog-post.html">investigate the performance of NVIDIA L40 GPUs for machine learning</a> benchmarked on the <a href="https://bede-documentation.readthedocs.io/en/latest/usage/index.html#grace-hopper-pilot">GH200 GPUs in Bede</a>.</p>

<p>The benchmark uses the <a href="https://huggingface.co/docs/transformers/en/index">HuggingFace Transformers</a> <a href="https://github.com/huggingface/transformers/blob/main/examples/pytorch/language-modeling/run_clm.py"><code class="language-plaintext highlighter-rouge">run_clm.py</code></a> example to train and evaluate the fine-tuning of the <a href="https://huggingface.co/openai-community/gpt2">GPT-2 124 million parameter LLM</a> using the <a href="https://huggingface.co/datasets/wikitext">WikiText-2 (raw)</a> dataset in FP32 and FP16 precisions.
Each benchmark was repeated <code class="language-plaintext highlighter-rouge">3</code> times, using a single batch size of <code class="language-plaintext highlighter-rouge">8</code>.
This batch size allows the benchmark to be repeated on GPUs with lower memory capacity, but larger batch sizes would likely improve performance for GPUs with sufficient memory, such as the GH200.</p>

<p>As of April 2024, pre-built binary wheels and conda packages for PyTorch for <code class="language-plaintext highlighter-rouge">aarch64</code> systems such as the GH200 do not include CUDA support.
Instead, the benchmark was containerised via <a href="https://apptainer.org/docs/user/main/introduction.html">Apptainer</a>, using containers based on the <a href="https://catalog.ngc.nvidia.com/orgs/nvidia/containers/pytorch">NGC PyTorch containers</a>.
Version <a href="https://docs.nvidia.com/deeplearning/frameworks/pytorch-release-notes/rel-24-02.html">24.02</a> was used for this benchmark, resulting in a software environment containing:</p>

<ul>
  <li>Python <code class="language-plaintext highlighter-rouge">3.10</code></li>
  <li>CUDA <code class="language-plaintext highlighter-rouge">12.3.2</code></li>
  <li>PyTorch <code class="language-plaintext highlighter-rouge">2.3.0a0+ebedce2</code></li>
  <li>HuggingFace Transformers <code class="language-plaintext highlighter-rouge">4.37.0</code></li>
</ul>

<p>The benchmark was then executed on <a href="https://docs.hpc.shef.ac.uk/en/latest/bessemer/cluster_specs.html#gpu-node-specifications">V100 GPUs in Bessemer</a>, <a href="https://docs.hpc.shef.ac.uk/en/latest/stanage/cluster_specs.html#gpu-nodes">A100 &amp; H100 PCIe GPUs in Stanage</a>, and the <a href="https://bede-documentation.readthedocs.io/en/latest/usage/index.html#grace-hopper-pilot">GH200 GPUs in Bede</a>.
Source files, instructions, job submission scripts and the generated results and figures can be found in the <a href="https://github.com/RSE-Sheffield/pytorch-transformers-wikitext2-benchmark">RSE-Sheffield/pytorch-transformers-wikitext2-benchmark GitHub repository</a>.</p>

<h4 id="fp32-results">FP32 Results</h4>

<p>The following figures and tables show the benchmark data for <strong>FP32</strong> training and inferencing on across a range of GPUs.</p>

<p>This includes the runtime training and inferencing phases in seconds (lower is better),
and the samples processing rate in samples per second (higher is better).</p>

<p>As you might expect, newer generations of GPU offer reduced application runtimes and increased performance compared to previous generations, with the GH200 outperforming the V100 SXM2 GPUs in Bessemer, the A100 SXM4 GPUs in Stanage and the H100 PCIe GPUs in Stanage.</p>

<p><img src="/assets/images/2024-05-08-bede-tier-2-hpc-nvidia-grace-hopper-superchip/ngc-pytorch-24.02-fp32-runtime.png" alt="Figure 2: FP32 Runtime (s)" /></p>

<p><img src="/assets/images/2024-05-08-bede-tier-2-hpc-nvidia-grace-hopper-superchip/ngc-pytorch-24.02-fp32-samples-per-second.png" alt="Figure 3: FP32 Samples per Second" /></p>

<table class="table table-bordered table-striped table-hovered">
  <thead>
    <tr>
      <th style="text-align: left">Metric</th>
      <th style="text-align: right">V100 SXM2</th>
      <th style="text-align: right">A100 SXM4</th>
      <th style="text-align: right">H100 PCIe</th>
      <th style="text-align: right">GH200 480GB</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left">FP32 Training Time (s)</td>
      <td style="text-align: right">733.447</td>
      <td style="text-align: right">204.360</td>
      <td style="text-align: right">181.747</td>
      <td style="text-align: right">114.210</td>
    </tr>
    <tr>
      <td style="text-align: left">FP32 Inference Time (s)</td>
      <td style="text-align: right">9.827</td>
      <td style="text-align: right">3.287</td>
      <td style="text-align: right">2.973</td>
      <td style="text-align: right">1.997</td>
    </tr>
    <tr>
      <td style="text-align: left">FP32 Training Samples per Second</td>
      <td style="text-align: right">9.481</td>
      <td style="text-align: right">34.028</td>
      <td style="text-align: right">38.261</td>
      <td style="text-align: right">60.886</td>
    </tr>
    <tr>
      <td style="text-align: left">FP32 Inference Samples per Second</td>
      <td style="text-align: right">24.413</td>
      <td style="text-align: right">72.932</td>
      <td style="text-align: right">80.666</td>
      <td style="text-align: right">119.908</td>
    </tr>
  </tbody>
</table>

<h4 id="fp16-results">FP16 Results</h4>

<p>The following figures and tables show the benchmark data for <strong>FP16</strong> training and inferencing on across a range of GPUs.</p>

<p>This includes the runtime training and inferencing phases in seconds (lower is better),
and the samples processing rate in samples per second (higher is better).</p>

<p>As with the FP32 results, the newer generations of GPU offer improved performance over older GPUs, with the GH200 out-performing the other models.
The relative performance difference will vary from workload to workload, with larger batch sizes likely showing increased performance.</p>

<p><img src="/assets/images/2024-05-08-bede-tier-2-hpc-nvidia-grace-hopper-superchip/ngc-pytorch-24.02-fp16-runtime.png" alt="Figure 4: FP16 Runtime (s)" /></p>

<p><img src="/assets/images/2024-05-08-bede-tier-2-hpc-nvidia-grace-hopper-superchip/ngc-pytorch-24.02-fp16-samples-per-second.png" alt="Figure 5: FP16 Samples per Second" /></p>

<table class="table table-bordered table-striped table-hovered">
  <thead>
    <tr>
      <th style="text-align: left">Metric</th>
      <th style="text-align: right">V100 SXM2</th>
      <th style="text-align: right">A100 SXM4</th>
      <th style="text-align: right">H100 PCIe</th>
      <th style="text-align: right">GH200 480GB</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: left">FP16 Training Time (s)</td>
      <td style="text-align: right">376.310</td>
      <td style="text-align: right">198.677</td>
      <td style="text-align: right">172.673</td>
      <td style="text-align: right">116.243</td>
    </tr>
    <tr>
      <td style="text-align: left">FP16 Inference Time (s)</td>
      <td style="text-align: right">5.723</td>
      <td style="text-align: right">3.290</td>
      <td style="text-align: right">2.893</td>
      <td style="text-align: right">2.147</td>
    </tr>
    <tr>
      <td style="text-align: left">FP16 Training Samples per Second</td>
      <td style="text-align: right">18.479</td>
      <td style="text-align: right">35.001</td>
      <td style="text-align: right">40.271</td>
      <td style="text-align: right">59.833</td>
    </tr>
    <tr>
      <td style="text-align: left">FP16 Inference Samples per Second</td>
      <td style="text-align: right">41.892</td>
      <td style="text-align: right">72.819</td>
      <td style="text-align: right">82.826</td>
      <td style="text-align: right">111.463</td>
    </tr>
  </tbody>
</table>

<h2 id="accessing-bede">Accessing Bede</h2>

<p>As a member organisation of the <a href="https://n8cir.org.uk/">N8 CIR</a>, Bede is available for use by an researchers at the University of Sheffield.</p>

<p>Access is granted on a per project basis, with the <a href="https://n8cir.org.uk/bede/accessing-bede/">N8 CIR Bede website providing instructions on how to apply for access</a> via the <a href="https://n8cir.org.uk/bede/bede-application/">online form</a>.
Once submitted, the application will be reviewed and if deemed appropriate and compatible with Bede the project will be created.</p>

<p><a href="https://bede-documentation.readthedocs.io/en/latest/">Bede’s online documentation</a> now includes GH200 specific information on the appropriate pages, in addition to the <a href="https://bede-documentation.readthedocs.io/en/latest/usage/index.html#grace-hopper-pilot">high level overview of the GH200 pilot</a>.
However, as there are only a limited number of GH200 GPUs in Bede at this time, jobs may spend a significant amount of time in the queue.</p>

<p>In addition to Bede, Sheffield researchers can also access a range of GPUs in our local Tier 3 facilities <a href="https://docs.hpc.shef.ac.uk/en/latest/bessemer/index.html">Bessemer</a> and <a href="https://docs.hpc.shef.ac.uk/en/latest/stanage/">Stanage</a>; as well as the <a href="https://docs.hpc.shef.ac.uk/en/latest/other-uk-hpc-resources/jade2.html">Tier 2 JADE HPC Facility</a>.</p>

<!-- Reference style links, to simplify reading the markdown -->]]></content><author><name>Peter Heywood</name></author><category term="Bede" /><category term="Grace-Hopper" /><category term="GH200" /><category term="GPU" /><category term="benchmarking" /><category term="PyTorch" /><summary type="html"><![CDATA[GH200 GPUs now available in N8 CIR Bede Members of the University of Sheffield have access to a range of GPU resources for carrying out their research, available in local (Tier 3) and affiliated regional (Tier 2) HPC systems. As of March 2024, the N8 CIR Bede Tier 2 HPC facility now includes an Open Pilot of 3 NVIDIA GH200 Nodes which are available to all users. Each GH200 node in Bede contains a single NVIDIA GH200 Grace Hopper Superchip - a 72 core NVIDIA Grace ARM CPU connected to a single NVIDIA Hopper GPU via a 900GB/s NVIDIA NVLink-C2C interconnect. This new interconnect allows data to be moved between the host and device with a much higher bandwidth than in traditional PCI-e based systems, reducing the time spent transferring data.]]></summary></entry><entry><title type="html">Upcoming : Git &amp;amp; GitHub through GitKraken - Zero to Hero!</title><link href="https://rse.shef.ac.uk/blog/2024-02-28-upcoming-git-zero-to-hero/" rel="alternate" type="text/html" title="Upcoming : Git &amp;amp; GitHub through GitKraken - Zero to Hero!" /><published>2024-02-28T12:00:00+00:00</published><updated>2024-02-28T12:00:00+00:00</updated><id>https://rse.shef.ac.uk/blog/2024-02-28-upcoming-git-zero-to-hero</id><content type="html" xml:base="https://rse.shef.ac.uk/blog/2024-02-28-upcoming-git-zero-to-hero/"><![CDATA[<p>The RSE Team are pleased to announce four scheduled sessions of the ever popular <a href="https://srse-git-github-zero2hero.netlify.app/">Git &amp; GitHub through
GitKraken - Zero to Hero!</a>. These courses will run <strong>in-person</strong> over
two consecutive days in morning sessions from 09:30 to 13:00 on the following days.</p>

<ul>
  <li><a href="/training/workshop/2024-03-18-git-zero-hero">Monday 18th/Tuesday 19th March 2024</a></li>
  <li><a href="/training/workshop/2024-04-22-git-zero-hero">Monday 22nd/Tuesday 23rd April 2024</a></li>
  <li><a href="/training/workshop/2024-05-20-git-zero-hero">Monday 20th/Tuesday 21st May 2024</a></li>
  <li><a href="/training/workshop/2024-06-24-git-zero-hero">Monday 24th/Tuesday 25th June 2024</a></li>
</ul>

<h2 id="what-are-git-github-and-gitkraken">What are Git, GitHub and GitKraken?</h2>

<p><a href="https://git-scm.com">Git</a> is a system of version controlling your code. Think of it as a lab-book or doctors notes that
are taken as you progress through your work, recording conditions, saving what has worked and correcting what doesn’t.</p>

<p><a href="https://github.com">GitHub</a> is a website that allows people to work collaboratively on version controlled code.</p>

<p><a href="https://www.gitkraken.com">GitKraken</a> is a client for working with Git and GitHub that includes both a GUI (Graphical
User Interface) and a CLI (Command Line Interface)</p>

<h2 id="who-is-the-course-for">Who is the course for?</h2>

<p>Everyone who writes code! If you write scripts to analyse your code in R, Stata or Matlab you would benefit from using
Git to version control your code and GitHub to share your code and make it open. If you write Python, JavaScript, C/++
code as part of a team in your research group you would benefit from using Git and GitHub to work together.</p>

<p>Getting started with these tools can be overwhelming but by taking this course you will be introduced to the concepts
behind them and how to use them effectively to not just version control your own work but work with others on the same
code.</p>

<p>The course material is available <a href="https://srse-git-github-zero2hero.netlify.app/">online</a> if you want to take a peek and
the first half using Git and publishing web-pages can be worked through in your own time. The real benefit comes from
participating in the collaborative exercises in the second half where you work together on projects making Pull Requests
and resolving problems that arise.</p>

<p>If you’ve never used Git, GitHub or GitKraken or have only just started then
<a href="https://mydevelopment.csod.com/ui/lms-learning-details/app/event/d4d09f67-097b-4451-8ddb-86cb90636c06">sign-up</a> and
come and learn more about these powerful tools.</p>]]></content><author><name>Neil Shephard</name></author><category term="git" /><category term="github" /><category term="gitkraken" /><summary type="html"><![CDATA[The RSE Team are pleased to announce four scheduled sessions of the ever popular Git &amp; GitHub through GitKraken - Zero to Hero!. These courses will run in-person over two consecutive days in morning sessions from 09:30 to 13:00 on the following days. Monday 18th/Tuesday 19th March 2024 Monday 22nd/Tuesday 23rd April 2024 Monday 20th/Tuesday 21st May 2024 Monday 24th/Tuesday 25th June 2024 What are Git, GitHub and GitKraken? Git is a system of version controlling your code. Think of it as a lab-book or doctors notes that are taken as you progress through your work, recording conditions, saving what has worked and correcting what doesn’t. GitHub is a website that allows people to work collaboratively on version controlled code. GitKraken is a client for working with Git and GitHub that includes both a GUI (Graphical User Interface) and a CLI (Command Line Interface) Who is the course for? Everyone who writes code! If you write scripts to analyse your code in R, Stata or Matlab you would benefit from using Git to version control your code and GitHub to share your code and make it open. If you write Python, JavaScript, C/++ code as part of a team in your research group you would benefit from using Git and GitHub to work together. Getting started with these tools can be overwhelming but by taking this course you will be introduced to the concepts behind them and how to use them effectively to not just version control your own work but work with others on the same code. The course material is available online if you want to take a peek and the first half using Git and publishing web-pages can be worked through in your own time. The real benefit comes from participating in the collaborative exercises in the second half where you work together on projects making Pull Requests and resolving problems that arise. If you’ve never used Git, GitHub or GitKraken or have only just started then sign-up and come and learn more about these powerful tools.]]></summary></entry></feed>